DeepSeek V4.1 Flash Deep Dive: Cache Optimization Is the Real Story

DeepSeek V4.1 Flash cuts Agent cache costs dramatically via asymmetric architecture — the real win for long-running AI tasks.
DeepSeek V4.1 Flash's core value isn't the price cut — it's the cache cost optimization for long-running Agent workloads. The model uses an asymmetric encoder-decoder structure with 552B total parameters (8B activated for input, 16B for output), reducing HBM requirements to 1/4 and SSD requirements to 1/8 versus the previous Flash. It natively supports multimodal input and 1M-token context, with time-of-day pricing where cache hits can be 50x cheaper than misses. Pro requests auto-migrate to Flash billing after September 14. Developers should validate using real tasks across output quality, latency, and actual cost.
DeepSeek's latest update has turned heads — but if you're only looking at the price cuts, you might be missing what actually matters. The release of V4.1 Flash is fundamentally about solving a high-value engineering problem: how to drive down cache costs when AI is running continuously. For developers building Agents that need multi-turn document reading and tool calls, that's where the real story is.
Native Multimodal + Million-Token Context: One Model for Text and Images
According to information confirmed on the official website, V4.1 Flash natively supports both image and text input, with a context length of up to 1 million tokens. This means image analysis and long-document processing can now be handled within the same model — no need to chain multiple models together or build complex preprocessing pipelines.
It's worth emphasizing: what's described here reflects officially published capabilities, not independently verified benchmarks. Real-world performance on tasks like image analysis or long-document processing still needs to be validated against your own use cases.
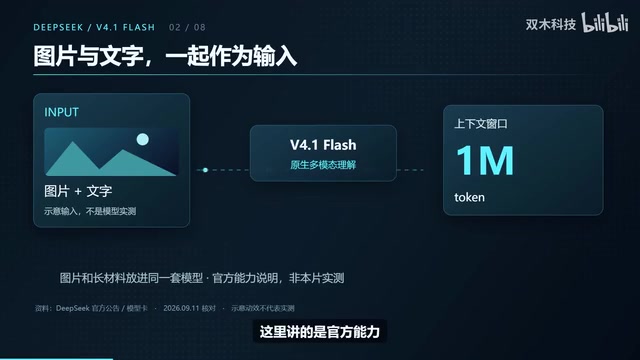
Architecturally, V4.1 Flash uses an asymmetric encoder-decoder structure with a total of 552 billion parameters. The key is its activation strategy: 8 billion parameters are activated during input processing, and 16 billion during output generation. Input and output are handled separately, rather than routing through the full parameter set every time — a design that directly serves the goal of reducing inference costs.
The "asymmetric encoder-decoder structure" mentioned here differs from a standard Transformer in an important way: in a standard Transformer, the encoding and decoding stages use the same scale of parameters, whereas the asymmetric design gives each stage a different number of active parameters. V4.1 Flash activates 8B parameters when processing input (encoding) and 16B when generating output (decoding). The logic: the computational intensity required to read and understand information is lower than what's needed to generate high-quality text — so you can save compute on the input side. The 552B total parameter count is made possible by a MoE (Mixture of Experts) architecture, where the model consists of many "expert" sub-networks, with only a small subset activated per inference pass. This lets an enormous parameter count coexist with relatively low actual compute overhead.
Cache Cost Optimization: The Real Highlight for Agent Scenarios
Why does this update deserve serious attention? The answer lies in how Agents actually work. As an AI reads documents and calls tools across multiple turns, it continuously maintains a context cache. In long-running Agent deployments, this overhead compounds over time and becomes the dominant cost driver.
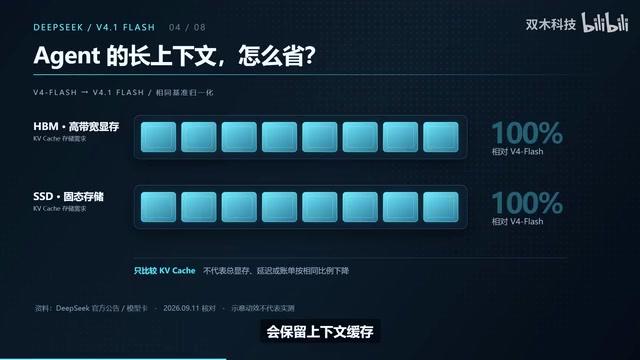
The official figures: compared to the previous-generation Flash, high-bandwidth memory (HBM) requirements drop to 1/4, and SSD storage requirements drop to 1/8. There's a nuance here that's easy to misread — what's shrinking is the cache footprint, not the total VRAM requirement for the entire machine. In other words, it optimizes storage pressure during continuous tasks, not the hardware threshold overall.
For use cases where Agents need to run continuously over extended periods, the practical significance of this optimization may far outweigh any per-token price reduction.
Understanding the "cache" here requires distinguishing two concepts. KV Cache (Key-Value Cache) is a core mechanism in LLM inference: for every token the model processes, it generates corresponding Key and Value vectors that are stored for reuse in subsequent generation steps, avoiding redundant computation. In multi-turn dialogue or long-context scenarios, this cache grows linearly with context length and consumes significant amounts of high-bandwidth memory (HBM, i.e., VRAM). The official claim of "HBM requirements reduced to 1/4" refers specifically to the storage volume of this KV Cache shrinking — likely achieved through quantization, compression, or structural changes. The reduction in SSD storage requirements corresponds to scenarios where the cache spills over to disk. For deployments where Agents run continuously for hours with ever-accumulating context, this directly affects how many concurrent tasks a single server can support.
Performance: Strong Benchmark Numbers, but With Caveats
On the performance side, official charts show V4.1 Flash scoring 74.2 on DPSAD — a notably strong result. However, in a separate terminal task benchmark, it did not outperform every other model in the comparison.
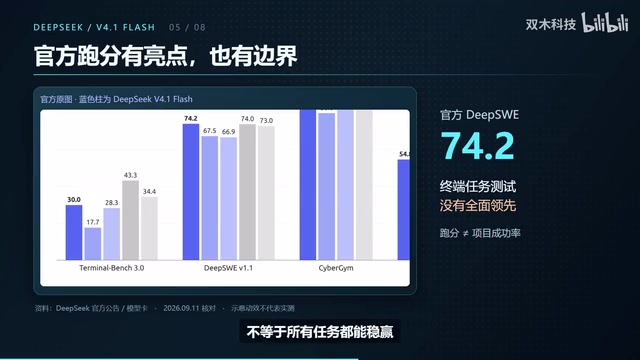
This detail is worth keeping in mind: a high score doesn't mean consistent performance across all tasks, and benchmark numbers can't be directly translated into success rates for your specific project. Benchmarks reflect capability ceilings under controlled conditions; real-world success rates depend on your specific task type, data distribution, and how you structure your calls. Treating benchmarks critically and validating against your own scenarios is always more reliable than blindly trusting leaderboards.
Pricing Structure and Migration Timeline
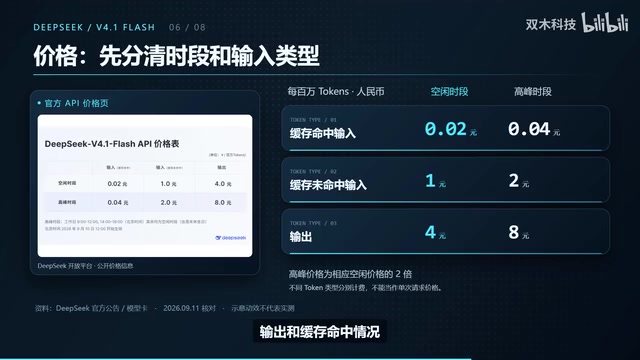
Looking at the official pricing page, V4.1 Flash uses a time-of-day pricing model (per million tokens):
Off-Peak Pricing
- Cache hit: ¥0.02
- Cache miss: ¥1
- Output: ¥4
Peak Pricing
- Cache hit: ¥0.04
- Cache miss: ¥2
- Output: ¥8
This pricing logic points to a clear optimization strategy: batch tasks that aren't time-sensitive can be scheduled during off-peak hours for significantly lower costs. Of course, actual expenses still depend on the volume of input and output tokens and your cache hit rate.
There's a critical date developers must be aware of: after 12:00 PM Beijing Time on September 14, existing Pro requests will automatically be routed to V4.1 Flash and billed at Flash rates — until V4.1 Pro officially launches. New users will go directly through the official DeepSeekAd Flash model endpoint. If your project depends on Pro, make sure to evaluate the cost and performance impact of this automatic migration in advance.
The 50x price gap between cache hits and misses during off-peak hours (¥0.02 vs ¥1) reflects the billing logic behind Prompt Caching. When your request prefix matches content already cached on the server, the platform can skip recomputation for that portion and reuse the result directly — hence the dramatically lower rate. For Agent applications with long system prompts or that repeatedly use the same documents as context, thoughtfully structuring your prompts so that frequently repeated content appears consistently at the beginning of requests is a key engineering practice for maximizing cache hit rates and taking full advantage of the low-cost tier.
Practical Advice: Validate with Real Tasks
Facing an update like this, the most pragmatic approach isn't to rush to conclusions — it's to roll up your sleeves and test. Take your typical workloads — image analysis, code editing, long-document processing — and run a complete comparison across three dimensions:
- Output quality: Does the new model's output meet your requirements?
- Response latency: Is the processing speed acceptable?
- Actual bill: What does the real cost look like, factoring in your cache hit rate?
The question worth asking about this update is whether it makes sustained Agent workloads meaningfully more cost-effective. If the multi-turn cache optimization delivers in real-world scenarios, it could bring structural cost improvements to long-running AI applications.
For developers, rather than being drawn in by the "price cut" headline, it's worth looking closely at the architectural design and caching mechanisms — that's where the true technical value of V4.1 Flash lies.
Related articles

A New Paradigm for Text Editing in Compose: TextFieldState Replaces the Old API
Jetpack Compose introduces the TextFieldState API to fix dropped characters and cursor jumps from async input. The old value/onValueChange callbacks will be deprecated in 1.13. This article covers InputTransformation, OutputTransformation, four state hoisting patterns, and new formatted text editing capabilities.

Remote Compose: A New Document-Driven Paradigm for Cross-Platform UI on Android
Remote Compose transmits compact binary documents instead of screen pixels, enabling efficient UI rendering on remote surfaces like Wear OS and widgets. This article covers its document creation API, expression animations, size optimization techniques, and Wear OS progress.

How Crashlytics Eliminates Android Memory and Responsiveness Issues
Through the Chroma Clip case study, this article explains how Firebase Crashlytics uses Application Exit Info, Profiling Manager, GWP ASAN, and ARM MTE to pinpoint ANRs, OOMs, memory limit terminations, and native memory corruption—solving the challenge of stack traces that don't point to the real culprit.