JOLT: One Model Plays Both Teacher and Student, Boosting Training Efficiency 6.5x

JOLT lets one model be both teacher and student, matching GRPO math reasoning accuracy with 1/6.5 the tokens.
The article introduces JOLT, a large model post-training method that has the same model play both teacher and student, with the teacher role specifically trained to produce feedback the student can digest and use, narrowing the representational gap between them. On the MATH benchmark, JOLT matches GRPO accuracy with about one-sixth the training tokens—if replicable, this would substantially change post-training cost structures. The article notes the result is limited to a single benchmark and source, with total FLOPs cost, teacher training overhead, capability degradation under shared parameters, and reward hacking risks all awaiting verification, and discusses potential impact on smaller teams and iteration speed.
The cost bottleneck of large model post-training often lies not in compute itself, but in the efficiency of training data utilization. Traditional reinforcement learning methods like GRPO require extensive sampling and trial-and-error, consuming an astonishing number of tokens. A recent study called JOLT proposes a new approach: letting the same model play both teacher and student, with the teacher trained to provide feedback the student can actually use—dramatically compressing the tokens needed for training.
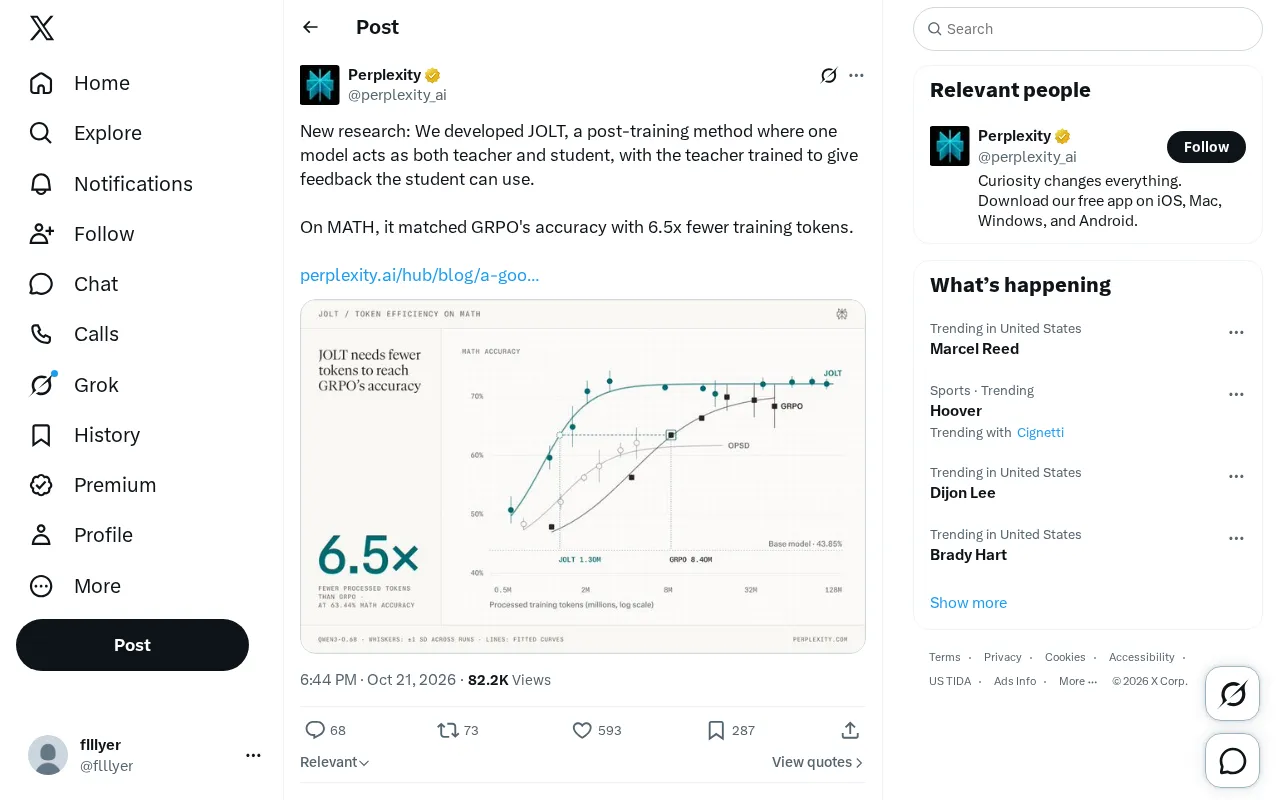
JOLT's Core Design: Teacher and Student United as One
The full name of JOLT is not disclosed in the original source material, but its mechanism is described clearly enough. In conventional teacher-student distillation or feedback learning, the teacher model and student model are typically two separate entities—the teacher evaluates or generates guidance signals, and the student learns from them. JOLT breaks this separation: the same model serves as both teacher and student.
The key point is that the teacher role does not naturally possess the ability to give effective feedback—it is specifically trained to do so. The research team trains the teacher component to generate feedback signals that the student can digest and utilize, rather than vague evaluations. This "feedback usability" training objective is what distinguishes JOLT from ordinary self-play methods.
From an information-theoretic perspective, this design reduces the representational gap between teacher and student—since they share the same parameter substrate, the distribution of feedback signals naturally aligns more closely with the student's current capability boundary.
Efficiency Data: What Does a 6.5x Token Reduction Mean?
According to the research team, on the MATH mathematical reasoning benchmark, JOLT achieves accuracy comparable to GRPO while consuming only about 1/6.5 of the training tokens.
This figure deserves closer examination. GRPO (Group Relative Policy Optimization) is the current mainstream method for reinforcement learning of large model reasoning capabilities, widely used for post-training on math and code tasks. Its efficiency has long been debated: it requires generating multiple sampled responses per question and computing group-relative advantages, with token overhead proportional to the number of samples. JOLT achieving equivalent accuracy with a 6.5x token reduction—if this result can be replicated on more tasks—would have a substantial impact on the cost structure of post-training.
It should be noted that the publicly available efficiency comparison is limited to the MATH benchmark alone, with a limited sample scope, and cannot yet be extrapolated to performance on code generation, multi-turn dialogue, or open-domain reasoning.
GRPO and Group-Relative Advantage
GRPO (Group Relative Policy Optimization) was proposed by the DeepSeekAd team in 2024 as a variant of PPO, designed specifically for post-training of LLM reasoning tasks. Its approach is to sample a group (typically 8–64) of responses to the same question, score them with a reward model or rules, then compute each response's relative advantage using the group average as a baseline—eliminating the need for a separate value network (critic) as in PPO. This reduces memory and model-size overhead, but at the cost of token consumption proportional to the sampling group size: each question requires generating multiple complete reasoning chains, an overhead that is particularly pronounced on long-chain reasoning tasks. JOLT's 6.5x reduction targets this structural cost rather than merely optimizing sampling implementation.
Positioning Relative to Existing Methods
JOLT is not the first work to attempt compressing post-training costs. Previous directions include rejection sampling fine-tuning, the Direct Preference Optimization (DPO) family of methods, and various self-rewarding mechanisms. JOLT's distinguishing features are twofold: first, teacher and student are unified; second, teacher feedback is specifically trained to suit the student.
Self-rewarding methods typically have the model score its own outputs, but misalignment between scoring ability and generation ability is a common failure mode—the model may give high scores to its own incorrect answers. JOLT mitigates this by training a teacher role, but exactly how it prevents reward hacking is not elaborated in the source material, and this is likely a technical detail worth focusing on in the paper.
Self-Rewarding and Reward Hacking
Self-rewarding refers to having a model evaluate or score its own outputs, thereby constructing training signals without external annotations. Its typical failure mode is reward hacking: the model learns to produce answers that easily receive high scores from itself rather than genuinely correct answers, causing scoring ability and generation ability to drift together and training signals to become distorted. Common mitigation approaches include introducing external reward models, separating scoring and generation roles, or imposing regularization constraints on scoring. JOLT's "specifically trained teacher role" is essentially artificially creating a role division on the same parameter substrate—conceptually close to the latter approach—but whether teacher-student parameter sharing reintroduces scoring-generation coupling is the key question for judging whether it can avoid reward hacking.
Open Questions Worth Watching
From the brief disclosure of a single source, several questions remain unanswerable. First, what is JOLT's absolute accuracy on MATH, and at what model scale was parity with GRPO achieved? Second, is the 6.5x token reduction achieved at the cost of more training steps or a more complex teacher training phase—total compute (FLOPs) and token count are not the same measure. Third, when teacher and student share parameters, is there a risk of capability degradation or mode collapse?
These are all critical to evaluating the method's practical viability, and await answers from the full paper and subsequent replication work.
Token Count and FLOPs Are Not the Same Measure
Large model training costs are typically measured in two ways: token count reflects data throughput, while FLOPs reflect actual floating-point operations, with the relationship between the two depending on model scale, sequence length, and the ratio of forward to backward computation. JOLT's reported 6.5x reduction is in token terms; if it requires an additional teacher training phase, more training steps, or multiple forward passes per step (teacher evaluation + student generation), the total FLOPs savings may be significantly less than 6.5x—or even inverted for smaller models. When evaluating such methods, wall-clock time, total FLOPs, and peak memory should all be reported simultaneously; otherwise, conclusions about "efficiency gains" can easily be amplified across different measures.
Potential Impact on Post-Training Practice
If JOLT's efficiency advantage generalizes, the most direct beneficiaries would be small-to-medium teams and academic labs—which are often constrained by token budgets and cannot afford GRPO-scale sampling. Reducing token requirements by an order of magnitude at equivalent accuracy means lowering the barrier to entry for reasoning capability post-training.
Another angle is iteration speed. The cycle of post-training experiments is largely constrained by sampling costs; improved token efficiency directly shortens the experimental feedback loop, allowing researchers to try more hyperparameter configurations and curriculum designs within the same budget.
Of course, until independent replication appears, these judgments remain speculative. Results from a single benchmark and a single source need more validation before becoming default choices in engineering practice.
One-line Summary
JOLT lets the same model serve as both teacher and student, achieving GRPO-equivalent math reasoning accuracy with 1/6.5 the tokens.
Paragraph Summary
This article introduces a large model post-training method called JOLT, whose core idea is to have the same model simultaneously play teacher and student, with the teacher role specifically trained to produce feedback signals the student can digest and utilize, thereby narrowing the representational gap between them. On the MATH mathematical reasoning benchmark, JOLT achieves equivalent accuracy to GRPO with about one-sixth of the training tokens—if replicable, this would substantially change the cost structure of post-training. The article also notes that the result is limited to a single benchmark and single source, with total FLOPs cost, teacher training overhead, capability degradation under shared parameters, and reward hacking risks all awaiting verification, and discusses its potential impact on small-to-medium teams and experimental iteration speed.
Related articles

Anthropic Files S-1: $16.3B Revenue, $80.7B Net Loss in Half a Year — Who Controls the Company?
Anthropic files S-1 for a Nasdaq IPO: H1 2026 revenue of $16.3B, an $80.7B net loss from valuation remeasurement rather than cash burn, founders' Class F shares holding 50.1% voting power, and no price or date yet.

Anthropic Files S-1: The Truth Behind $16.3B Revenue and $80.7B Loss
Anthropic's S-1 reveals $16.3B revenue and $80.7B net loss in H1 2026, with $72.4B from accounting effects. The filing also discloses $265.6B compute commitments, cloud deal details, and a 50.1% founder voting control structure, while IPO pricing remains blank.

Anthropic Financials Leaked: Revenue Far Exceeds Compute Costs, Claude Inference Gross Margin Hits 68%
Leaked Anthropic financials show revenue roughly twice total compute costs, Claude inference gross margin at 68%, while frontier training burns $2.8B per quarter. This article breaks down the two accounts and analyzes shifts in AI company valuation logic.