MOVO AI: The First Long-Form Video AI Agent on Mobile

MOVO AI positions itself as a mobile long-form video AI Agent, replacing professional editing workflows with chat-based delegation.
MOVO AI is positioned as "the world's first long-form video AI Agent for mobile," aiming to compress the long-form video creation chain—scripting, storyboarding, generation, editing—into a single conversation. Users can start by shooting, uploading footage, or simply providing an idea; the Agent handles planning, generation, and iteration, with core selling points being character and scene consistency and chat-based interaction replacing prompts and canvas workflows. Background continuation after screen lock shifts it from operation-intensive to delegation-intensive. It received 150 upvotes and 21 comments on Product Hunt launch day, ranking #2, but its maximum duration, modification granularity, and compute costs remain undisclosed and need hands-on verification.
Long-form video creation has always been a high-barrier endeavor—scripting, storyboarding, sourcing footage, editing, color grading—every step relies on professional tools and a great deal of time. MOVO AI attempts to compress this entire chain into a single conversation using an "Agent" approach, and it places its main battleground on mobile.
What It's Trying to Solve, in One Sentence
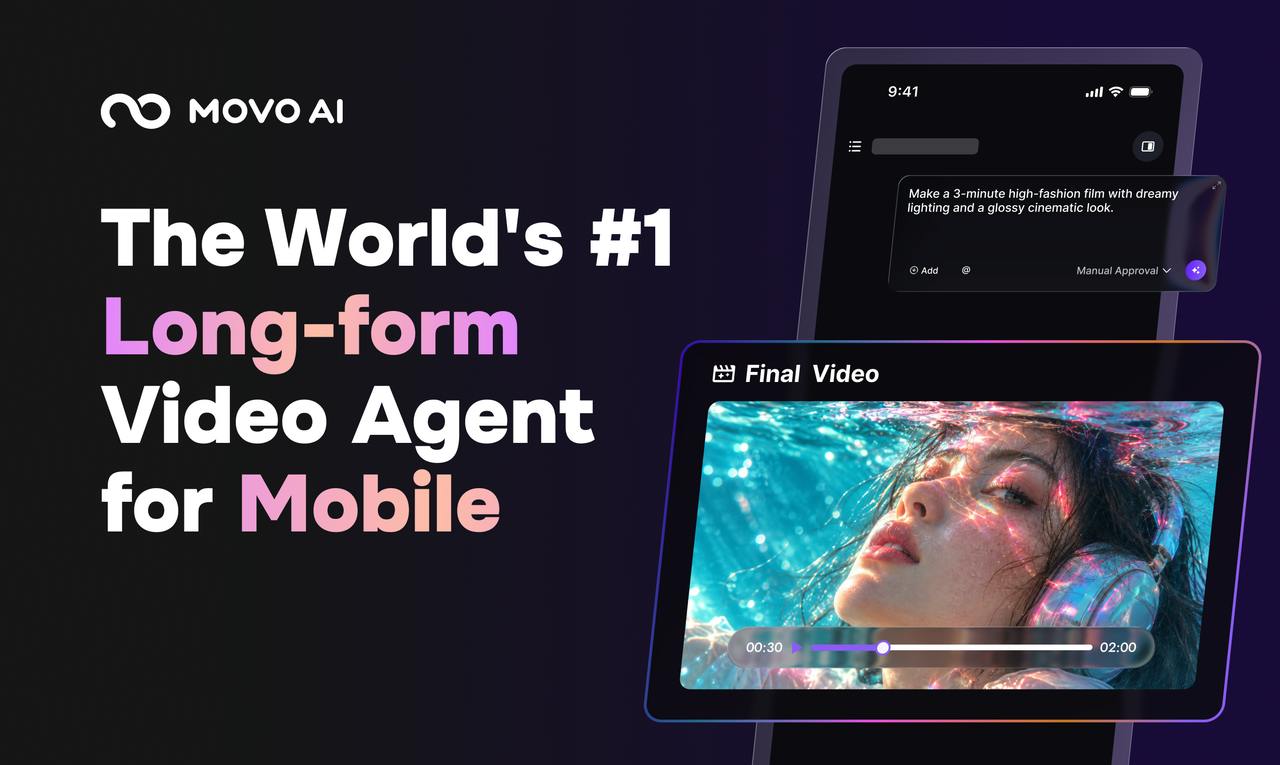
MOVO AI's official positioning is "the world's first long-form video AI Agent for mobile." Note the two qualifiers: long-form video and mobile. The former means it's not content with generating a few-second clip—it aims to maintain character, scene, and narrative coherence across a complete work. The latter means it directly abandons the complex timeline and canvas workflows of desktop, shrinking the interaction down to a chat box.
According to its Product Hunt page, the product received 150 upvotes and 21 comments on launch day, ranking #2 for the day. For an AI product positioned as a tool, this level of engagement shows it has struck a real need among creators for "mobile long-form video production."
From Shooting to Final Cut, the Agent Takes Over the Middle
MOVO AI's input methods are flexible: you can shoot on the spot, upload existing footage, or simply provide an idea. Then you just tell it what you want in natural language, and the Agent plans, generates, and iterates on its own, maintaining character and scene consistency throughout the process.
The key differentiator here is "consistency." Short-video generation models typically only need to ensure image quality within a single shot, whereas long-form video requires the same character to look like the same person across different shots and scenes. MOVO AI explicitly highlights this as a selling point, indicating it has made targeted design efforts in character preservation and scene coherence.
The official description also includes a very candid statement: no "prompt gymnastics," no canvas-style heavy workflows, and no manual stitching of clips. This is essentially addressing the three pain points of existing AI video tools—high prompt barriers, complex interfaces, and tedious post-production assembly.
Character Consistency is a core technical challenge in the AI video generation field. In short-video generation, the model only needs to ensure the image is plausible within a single shot. But in long-form video, the same character appears across different shots, scenes, and lighting conditions, and the model must ensure that facial features, hairstyle, clothing, body type, and other attributes remain stable across shots. Common industry approaches include: locking a character reference image before generation, using identity-preserving loss to constrain the diffusion model, or anchoring and reusing character features in latent space. The strength of character consistency directly determines whether AI-generated content can move from "showcase clips" to "usable narrative works."
Lock Screen Without Interruption: The Real Value of the Agent Form
The detail that best embodies the "Agent" attribute is this: lock your phone, and MOVO AI keeps working in the background. When you return, you review progress and request changes via chat.
This may seem minor, but it actually changes the rhythm of creation. Traditional video tools require users to stay present watching the render bar the entire time, whereas the Agent model allows you to "assign the task—walk away—come back to review." It pushes video production from "operation-intensive" toward "delegation-intensive," which is also the core characteristic that distinguishes AI Agent products from ordinary generation tools.
The core difference between an AI Agent and an ordinary generation tool lies in "autonomy" and "persistence." An ordinary generation tool follows a "request—response" pattern: the user initiates a generation, waits for the result, then manually initiates the next one. An Agent, by contrast, has task planning, multi-step execution, state memory, and background continuation capabilities—it can break down a large goal like "make a three-minute short film" into subtasks such as script generation, storyboard design, segment-by-segment generation, and consistency validation, and keep pushing forward unattended. Continuing to work in the background after the screen is locked is precisely the embodiment of Agent persistence. This model is especially important for long-form video, because long-form generation takes far longer than short video; if users were required to stay present the whole time, the creative experience would be extremely inefficient.
Mobile-First, But Not Only Mobile
MOVO AI also offers a Web version. The mobile end handles quick starts and fragmented-time management, while the Web end may take on more detailed review and adjustment. This dual-end strategy is becoming increasingly common among AI creation tools: first use mobile to lower the startup cost, then use the web to handle deep operations.
However, the product is currently listed under the iOS category, and whether Android users will get an equivalent experience is not clearly stated in the official information.
Prompt Gymnastics is a playful term in the AI creation community, referring to the process in which users must repeatedly experiment and stack large numbers of qualifiers and negative prompts to get the model to produce the desired result. In AI video, prompt gymnastics is especially severe: users need to precisely describe camera movement, lighting, character actions, visual style, and other dimensions, and a slight omission can cause the generated result to deviate from expectations. MOVO AI's claim that prompt gymnastics is not needed implies that its Agent layer performs intent understanding and automatic completion—users only need to give a high-level description, and the Agent translates it into detailed instructions the model can execute. This lowers the barrier to use, but also places higher demands on the Agent's understanding accuracy and fault tolerance.
A Few Questions Worth Watching
Generation quality and maximum duration: The official materials do not define what counts as long-form video, nor do they disclose image quality parameters. How well character consistency holds and at what length drift begins require actual use to judge.
Granularity of modifications: Chat-based editing sounds smooth, but video is highly structured content. When a user says "the third segment is too fast," whether the Agent can precisely locate it and change only that segment—without redoing the entire film—is the dividing line for the experience.
Compute and cost: Long-form video generation consumes far more compute than short clips, and free quotas, subscription pricing, and queueing mechanisms will directly affect whether it can become an everyday tool.
Conclusion
MOVO AI's product thinking is clear: instead of competing with professional editing software on feature depth, it uses an Agent to wrap the entire process from idea to final cut, and places the entry point on the device users hold in their hands most often. The results of 150 upvotes and a #2 ranking for the day show that this direction resonates. The real test is whether, when the video becomes long enough to tell a complete story, its consistency preservation and precise editing capabilities can live up to the words "long-form video."
One-line Summary
MOVO AI positions itself as a mobile long-form video AI Agent, replacing professional editing workflows with chat-based delegation.
Paragraph Summary
MOVO AI is positioned as "the world's first long-form video AI Agent for mobile," attempting to compress the long-form video creation chain—scripting, storyboarding, generation, editing—into a single conversation using an Agent approach. Users can start by shooting, uploading footage, or simply providing an idea; the Agent automatically handles planning, generation, and iteration. Its core selling points are maintaining character and scene consistency and replacing prompts and canvas workflows with chat-based interaction. Background continuation after screen lock shifts it from operation-intensive to delegation-intensive. The product received 150 upvotes and 21 comments on Product Hunt launch day, ranking #2 for the day. However, its maximum long-form duration, modification granularity, and compute costs have not been disclosed and require hands-on verification.
Related articles

Will GitHub Die? Open Source Maintainer Burnout and the Collaboration Crisis in the AI Era
Lex Fridman podcast discussion on open source maintainer burnout and GitHub's predicament: massive pull requests overwhelm core maintainers, and AI worsens code bloat. Using math journal peer review and Poincaré conjecture verification as analogies, the article analyzes why verification in knowledge production must be deliberately slow, and how open source communities can avoid the failure mode of maintainers exiting.

Stop Building Cookie-Cutter AI Websites: 3 Tools That Transform Your Coding Agent
Three tools that boost AI coding agents: FFmpeg skill for local video editing in Claude Code and Cursor, Hallmark's 50 design themes to fix cookie-cutter AI sites, and Jailbreaks' 25+ model prompts.

How America's Gerontocracy Squeezes the Younger Generation
Americans over 55 hold nearly three-quarters of national wealth, alongside an 80-year-old president and elderly congressional leaders. The Atlantic's Idrees Kahloon explains how gerontocracy drives up housing costs, squeezes opportunities for the young, and explores zoning reform and child poverty reduction as practical fixes.