Mythos 5.1 Early Access: A New Model Being Called a "Monster"

A Reddit user calls Mythos 5.1 a "monster" after early access, but offers no benchmark data to back it up.
A Reddit user who gained early access to Mythos 5.1 described it as a "monster," sparking interest in the AI community. However, the post offers only a brief subjective impression — no specific test scenarios, no quantifiable benchmarks, and no comparative data. Based on the version number, 5.1 likely represents an iterative improvement over 5.0 rather than a major architectural shift. The article urges readers to treat the "monster" label as an intriguing signal rather than a definitive conclusion, and to wait for concrete use-case testing, reproducible results, and stability data before drawing firm judgments.
Early Access Report from Reddit
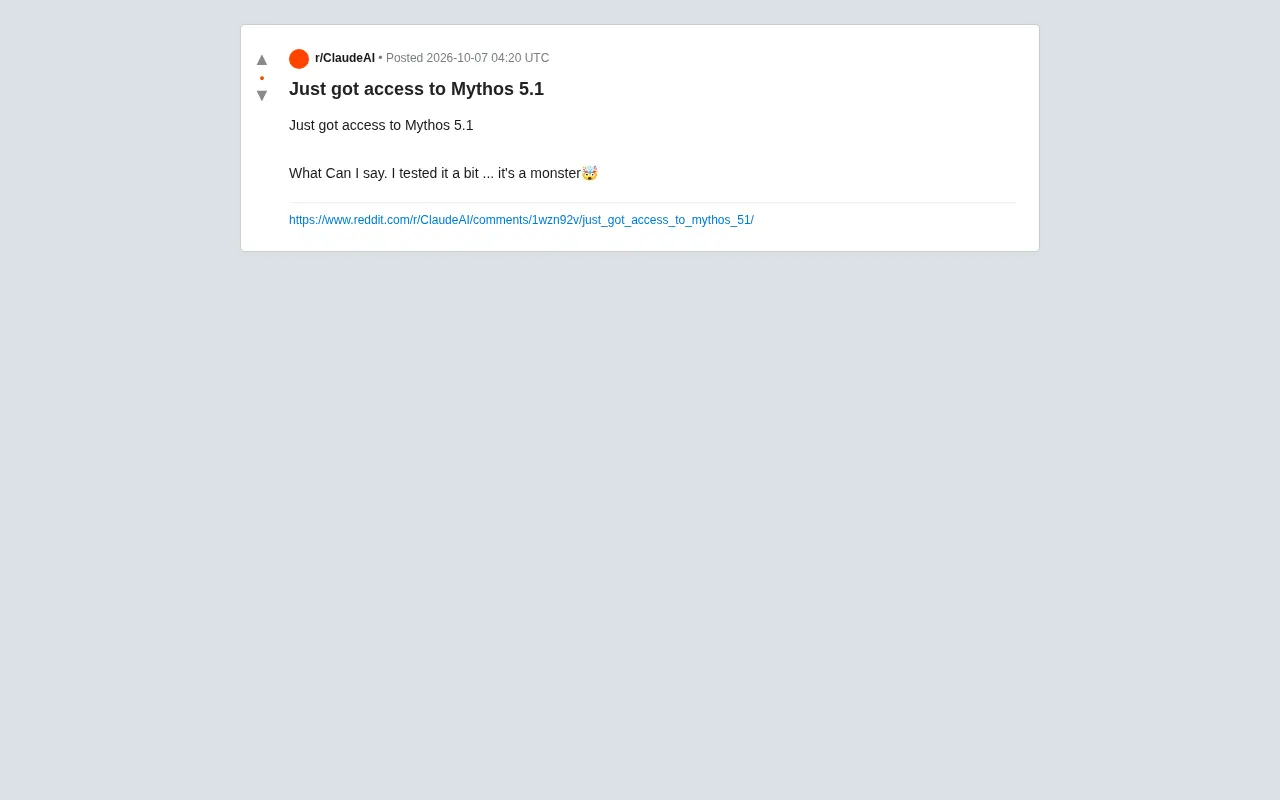
A Reddit user recently posted about gaining access to Mythos 5.1, sharing their first impression in a brief but blunt way: "It's a monster." The post itself is light on details — the user mentioned they "tested it a bit" — but the tone of genuine surprise suggests the model exceeded their expectations.
This kind of early access post is nothing new in the AI community. Development teams and platforms typically open new versions to a small group of users first, gather real-world feedback, and then gradually expand availability. This limited rollout of Mythos 5.1 is a textbook example of that kind of staged release.
How to Interpret a "Monster" Rating
In AI community parlance, calling something a "monster" is usually a compliment — a way of saying a model clearly outperforms its peers in capability, speed, or overall performance. That said, a single subjective reaction tells us very little about Mythos 5.1's actual strengths. The post includes no specific test tasks, no quantifiable benchmark scores, and no comparative results.
Looking at the version number, 5.1 suggests an iterative update built on 5.0 — typically implying performance optimization, bug fixes, or targeted capability improvements rather than a ground-up architectural overhaul. Without official documentation, though, that remains an educated guess based on naming conventions.
Gray-area or staged releases (also known as canary releases or progressive rollouts) are a common deployment strategy in software: a new version is opened to a tiny subset of users first, real-world feedback is collected to surface potential issues, and coverage is gradually expanded until full release. For AI models, this phase is especially important — because how a model performs on diverse, real-world prompts often differs from internal test set results. That's precisely why community-sourced first-hand reports during a staged rollout can occasionally provide a useful perspective beyond official benchmarks, while also being prone to bias due to extremely small sample sizes.
What Readers Should Do: Stay Curious, Stay Grounded
For users tracking the cutting edge of AI tooling, early signals like this are worth noting — but not worth over-indexing on. A well-grounded assessment should be built on:
- Specific use cases: Does the model shine in code generation, long-context comprehension, or multimodal tasks?
- Reproducible test results: Are there benchmark scores or side-by-side comparisons with leading models?
- Stability and availability: Early versions often come with access limits, inconsistent response times, and other rough edges.
Until that information surfaces, "monster" reads more like an intriguing teaser than a definitive verdict. If you're interested in the Mythos series, the best move is to follow community discussions and watch for official updates — and then reassess once more real-world data is available.
Benchmarks are standardized tools for measuring AI model capabilities. Common ones include MMLU (Massive Multitask Language Understanding), HumanEval (code generation), MATH (mathematical reasoning), and the Needle-in-a-Haystack test for long-context handling. Each benchmark targets different capability dimensions, so no single score captures a model's full picture. There's also the risk of benchmark contamination — if training data includes test questions, scores can be artificially inflated. When evaluating a new model, it's best to look across multiple independent benchmarks and combine that with community feedback from real-world workflows. Neither source alone tells the whole story.
Takeaway
At its core, this post is a classic example of early community word-of-mouth: enthusiastic, brief, and deeply subjective. It reflects high expectations for Mythos 5.1 — but it's also a reminder that in a landscape where new AI tools arrive constantly, real value judgments still need to be grounded in solid testing and data.
Related articles

Anthropic Files S-1: $16.3B Revenue, $80.7B Net Loss in Half a Year — Who Controls the Company?
Anthropic files S-1 for a Nasdaq IPO: H1 2026 revenue of $16.3B, an $80.7B net loss from valuation remeasurement rather than cash burn, founders' Class F shares holding 50.1% voting power, and no price or date yet.

Anthropic Files S-1: The Truth Behind $16.3B Revenue and $80.7B Loss
Anthropic's S-1 reveals $16.3B revenue and $80.7B net loss in H1 2026, with $72.4B from accounting effects. The filing also discloses $265.6B compute commitments, cloud deal details, and a 50.1% founder voting control structure, while IPO pricing remains blank.

Anthropic Financials Leaked: Revenue Far Exceeds Compute Costs, Claude Inference Gross Margin Hits 68%
Leaked Anthropic financials show revenue roughly twice total compute costs, Claude inference gross margin at 68%, while frontier training burns $2.8B per quarter. This article breaks down the two accounts and analyzes shifts in AI company valuation logic.