PewDiePie's Homemade Local AI Model AJAX: A Privacy Experiment Against Surveillance

PewDiePie built a local AI model called AJAX, turning a frustration-filled experiment into a lesson on distillation, privacy, and small models.
YouTuber PewDiePie fine-tuned a local AI model called AJAX on his own Odysseus framework, emphasizing fully local operation, privacy, and uncensored output. The journey was rocky: a fan crowdsourcing campaign for training data was nearly ignored, revealing the real difficulty of voluntary data collection; attempts to use knowledge distillation from an OpenAI model led to two account bans. Using open-source Red Team tools to ablate the model's refusal mechanisms, he noted the trade-off of capability degradation while drawing a firm ethical line against causing harm. The finished AJAX handles everyday tasks like email and calendars, and PewDiePie's core message is clear: small models trained for specific tasks offer unique value far exceeding cloud-based giants in cost and privacy.
YouTube legend PewDiePie, with over 100 million subscribers, recently published a highly talked-about technical project on various platforms — he personally fine-tuned a local AI model called AJAX. Despite its tongue-in-cheek name (a nod to the cleaning product brand), the project represents a genuinely serious hands-on exploration of local AI, data privacy, and model training.
From Odysseus to AJAX: A YouTuber's Technical Evolution
PewDiePie had previously developed a framework called Odysseus, designed to simplify the process of running AI locally. AJAX is a model fine-tuned on top of the Odysseus framework. Its core selling point is fully local operation: it can browse the web for private searches, draft emails, and manage calendars and to-do lists.
He repeatedly hammered home one point: many of the privacy and censorship frustrations people encounter when using AI can simply be solved by running the model locally. Unlike the cloud-based large models from OpenAI and Anthropic that require massive compute, AJAX is a very small model, designed so that ordinary people can run it on their own computers and experience the joys of local AI.
Notably, he also shared his take on the "AI will replace programmers" narrative. Even if developers are using AI to write code, he argues, what companies truly need are people who can read and understand code and think like engineers — mastering the fundamentals of programming matters more now than ever.
The Crowdsourcing Fiasco: Nobody Wanted to Donate Data
The most dramatic episode in the AJAX project was PewDiePie's attempt to crowdsource training data from his fans. Because Odysseus is a private, first-party-controlled project that collects zero user data, he came up with what seemed like a brilliant idea — actively asking fans to contribute data rather than silently scraping it the way tech giants do.
He even built a dedicated data submission platform and recorded a tutorial, fully expecting data to pour in. Almost nobody showed up. He joked it was "the closest I've come to crying in a long time." This darkly comedic episode perfectly illustrates the real-world difficulty of crowdsourcing high-quality training data — even a creator with a massive fanbase can't easily get users to contribute structured data voluntarily.
Knowledge Distillation and Getting Banned by OpenAI Twice
To improve the small model's performance, PewDiePie employed knowledge distillation — extracting knowledge by training against a larger model. He had his eye on one of OpenAI's reasoning models, but hit a wall: OpenAI had encrypted the reasoning tokens (the intermediate problem-solving steps within the chain of thought).
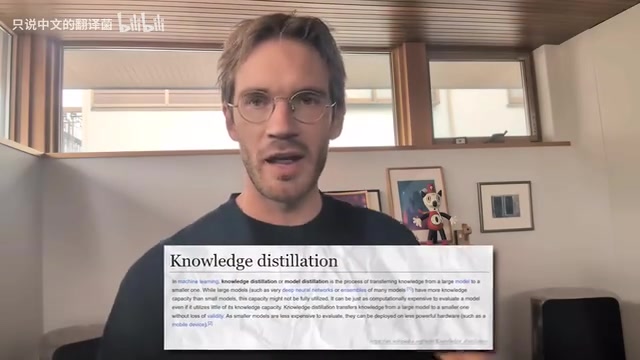
He mentioned finding a research method that used OpenAI's own API to decrypt this data, and that it "worked" — though he jokingly emphasized this violated the Terms of Service and he would "never do such a thing." In the course of building the model, OpenAI banned his account twice, citing failed verification. This experience also reflects just how sensitive closed-source model companies are about data scraping and distillation.
Knowledge Distillation is a model compression technique systematically formalized by Hinton et al. in 2015. The core idea is to use a large, pre-trained "teacher model" to guide the training of a smaller "student model" — the student learns not just from hard labels (correct answers), but also from the probability distributions output by the teacher (soft labels), gaining richer supervisory signals. Intuitively, the teacher assigns non-trivial probabilities to similar categories during inference; this "dark knowledge" contains far more structural information than simple 0/1 labels. For language models, distillation typically means having the small model mimic the large model's output text or internal representations to "inherit" its reasoning capabilities. OpenAI's move to encrypt reasoning tokens (thinking tokens) is precisely aimed at preventing external developers from accessing the intermediate chain-of-thought steps via the API, thereby blocking the low-cost distillation of competitive models.
Uncensoring and the Question of Ethical Boundaries
Another core feature of AJAX is unrestricted output (de-censorship). PewDiePie shared an interesting technical detail: the model's "refusal mechanism" (the AI's ability to say "no") isn't concentrated in a single region of the weights — it's distributed throughout the entire network.
He used the analogy of "doing an MRI on the brain" to describe the process — you feed the model a large volume of conversations it "doesn't want to answer," identify and ablate the refusal components, and the more you remove, the more "brain damage" you cause to the model. He used an open-source Red Team tool to streamline this workflow.
PewDiePie also acknowledged that the de-censorship process forced him to think about ethical boundaries. There are already countless uncensored models out there, so whether this one has restrictions hardly matters in the grand scheme — but the line he ultimately drew was: don't use it to harm others or yourself. This aligns with his personal philosophy, and he repeatedly reminded users to "use it carefully and responsibly."
The model's "refusal mechanism" technically originates from RLHF (Reinforcement Learning from Human Feedback) and safety fine-tuning: trainers use large volumes of annotated data to teach the model which requests to refuse, encoding these signals into the neural network weights — not stored in any isolated module, but diffused across the entire network's activation pathways. Common approaches to de-censorship (unalignment/abliteration) include: targeted removal of attention heads or MLP direction vectors associated with refusal behavior, reverse fine-tuning on uncensored datasets, or using adversarial prompts to make the model "forget" refusal patterns. Open-source community Red Team tools (such as llm-attacks and FastChat's adversarial testing modules) can automatically generate jailbreak prompts and evaluate model boundaries. The more thorough the de-censorship, the greater the weight perturbation in those dimensions, which typically leads to varying degrees of degradation in capabilities like language fluency and logical consistency — exactly what PewDiePie described as "brain damage."
The Small Model Philosophy: Built for Specific Tasks
AJAX version one was ultimately finished. In PewDiePie's words, it "may have suffered a little brain damage," but it's still "a very beautiful piece of work" — capable of sorting inboxes, browsing the web, and managing calendar to-dos, "working correctly 9 out of 14 times."

He shared an interesting back-of-the-envelope calculation: to run a trillion-parameter model like those from OpenAI or Anthropic locally, he roughly estimated it would require 27 instances of his current computer, consuming electricity equivalent to roughly 150 houses. In his view, using such a behemoth just to "check your email" makes absolutely no sense.
This is the belief he holds firmly — small models trained for specific tasks have their own intrinsic value. AJAX isn't meant to replace human creativity and thinking; it's there to help you quickly research, browse, and retrieve information, saving time when processing large volumes of data. He's currently continuing to train the model with GRPO (a reinforcement learning method), which has been running for several days, and he plans to release major updates to both Odysseus and AJAX.
GRPO (Group Relative Policy Optimization) is a reinforcement learning optimization algorithm proposed by the DeepSeekAd team in 2024, and an improved variant of PPO (Proximal Policy Optimization). Traditional PPO requires a separate value network (critic) to estimate baseline rewards when training language models, which is computationally expensive. GRPO's improvement lies in sampling a group of outputs for the same input and using the average reward of outputs within the group as the baseline, eliminating the need for an independent critic model and significantly reducing memory usage and training costs. This makes GRPO especially well-suited for individual developers with limited resources doing reinforcement learning fine-tuning on small models. Models like DeepSeek-R1 made heavy use of this approach during training, and it has since been widely adopted by the open-source community for capability alignment experiments on local models. PewDiePie's use of GRPO for ongoing AJAX training is a textbook example of how small-model reinforcement learning fine-tuning is being practiced today.
Closing Thoughts
The significance of the AJAX project may lie less in whether it's a top-performing model, and more in how it uses a lighthearted — even self-deprecating — approach to introduce the public to cutting-edge topics like local AI, knowledge distillation, model de-censorship, and the value of small models. PewDiePie used his signature storytelling style to turn a technically frustrating experience (failed crowdsourcing, two account bans) into a public conversation about data privacy and AI autonomy. For anyone following the local AI trend, this is an experiment well worth trying — and well worth thinking about.
Related articles
AWS AgentCore Gateway: Connecting AI A…
AWS AgentCore Gateway: Connecting AI Agents to Enterprise Backends with MCP
How AWS AgentCore Gateway acts as a primary MCP server to aggregate REST APIs, Lambda, and existing MCP services? Analyzing its AST real-time mapping, zero cold start, semantic search for tool overload, session isolation, and key injection security design, plus the architectural approach to decoupling enterprise AI agents from backends.

One Link Gives Figma AI a New Skill: Hands-On with MCP Connectors
Paste one MCP server link and the AI Agent in Figma gains new tool capabilities. We break down the setup flow, 20+ one-click apps, read/write permissions and execution policies, and the public HTTPS requirement.

Cognition SWE-2 in Practice: One Prompt to Handle the Whole Product Launch Process
Analyzing a YouTube creator's prompt for using Cognition SWE-2 to launch a product: a landing page, seven-email sequence, and non-buyer follow-up tool, plus how the 'test and report' constraint changes AI delivery quality.