Qwen3 8B-27B Local Deployment Test: Hardware Requirements, Speed, and Real-World Performance

Qwen3.8-27B approaches top online models in quality, but its dense architecture makes local deployment costly and slow.
Alibaba's Qwen3.8-27B is a dense multimodal model that activates all 27B parameters on every inference pass, making it far more VRAM-hungry than equivalent MoE models. Real-world tests across machines from a ¥4,000 dual-V100 build to an ¥110,000 RTX Pro 6000 found: 24GB VRAM barely gets by, 48GB is the practical minimum, and the 96GB full-precision version scores 76 points — surpassing GPT-5.5. Speed-wise, Qwen3.8 is noticeably slower than its predecessor, dual-card setups struggle with long contexts, and even MacBook Pro Max's 96GB unified memory only yields 5 tokens/sec.
Alibaba's Qwen series returns with its first open-source release in four months. The newly launched Qwen3.8-27B immediately sparked heated discussion in the open-source community. Official benchmarks show this locally-deployable 27B dense multimodal model can go head-to-head with OPUS 4.6 across multiple text and vision tests. But do the numbers hold up in the real world? One Bilibili content creator ran tests across three machines — from a ¥4,000 budget build all the way to a six-figure workstation — and put together a genuinely useful hands-on report.
Qwen3.8 Architecture: The Performance and Price of a Dense Multimodal Model
Qwen3.8 carries forward the architecture from the 3.5 generation, with the core upgrade being agentic reinforcement learning in real environments — the model can autonomously decide its next action based on different engineering states. This is especially critical for complex tasks like coding.
One key detail: this generation's 27B is still a dense multimodal model, meaning all 27 billion parameters participate in every single token generation. The maximum context window stays at 256K, matching the previous generation — no breakthrough to 1M, which is a mild disappointment.
The dense architecture is the biggest pain point for local deployment. For comparison, DeepSeekAd V4 Flash has 284B parameters (about 10× larger), but its MoE architecture only activates 13B parameters per inference pass. With Qwen3.8-27B, all 27B parameters activate every time — making its actual computational load more than twice that of the competition. This directly determines its demanding hardware requirements.
The Hardware Ladder: VRAM Requirements from 24GB to 96GB
Running Qwen3.8-27B locally comes with unavoidable hardware costs. The creator laid out a clear VRAM tier guide, recommending GPU-first setups for optimal speed.
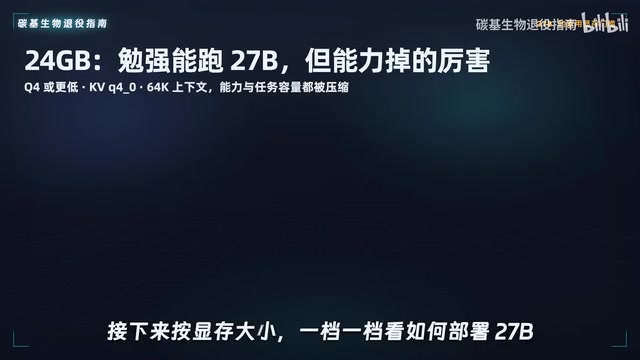
24GB VRAM: Runs, but Don't Expect Much
This corresponds to an RTX 4090 or lower-spec 5090 — the absolute minimum to run 27B. At this tier, the model can only be quantized to Q4 or lower, KV cache requires 4× quantization, and context is hard-capped at 64K. At this level of quantization, model capability degrades noticeably, and 64K context falls well short of practical needs.
32GB VRAM: Trade-offs Begin
This covers the full-spec RTX 5090 or dual 16GB cards. Quantization can reach Q5, and context can be opened up to 256K — but you can only pick two out of three: vision, MTP, and 8-bit KV. You'll need to prioritize based on your use case.
48GB VRAM: No More Compromises
At this tier, quantization can reach Q6 or even Q8, and 256K context, 8-bit KV, vision, and MTP can all be enabled simultaneously. This is where 27B truly enters a genuinely usable operating range.
96GB VRAM: Two Paths — Quality or Throughput
At the top tier, you can choose between the BF16 full-precision original (maximum quality, full-precision KV retained) or Q8 quantization to free up VRAM for vLLM to handle more concurrent requests (throughput-first).
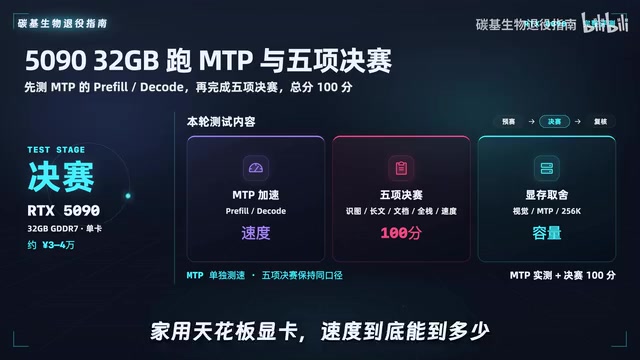
Worth noting: the 5090's 32GB version falls just barely short of being able to enable everything — a frustration for many enthusiasts.
The Speed Trap: Expensive Cards Don't Always Mean Faster Inference
Even with the right hardware, speed may still disappoint. Running Qwen3.8-27B on a MacBook Pro Max with 96GB unified memory yielded only 5 tokens per second — as a developer, that's at least three times too slow to be practical.
On a self-built ¥4,000 dual V100 machine, Qwen3.8 showed a noticeable speed drop compared to the previous 27B generation: only 25 tokens/sec on short contexts, dropping to 12 tokens/sec on long ones. Two key takeaways:
- Qwen3.8 is slower than 3.6: Prefill and inference speeds dropped roughly 40% and 20% respectively; the community hasn't reached consensus on why.
- Long-context performance degrades significantly: The longer the context, the more data needs to be read per token, plus repeated synchronization between dual cards.
This also exposes the pitfalls of dual-card deployment: two 16GB cards are not equivalent to a single 32GB card. At 256K context, the MTP draft model hits OOM, and VRAM distribution across two cards is highly uneven — once the card hosting the draft model fills up, the other card's available space can't be utilized.
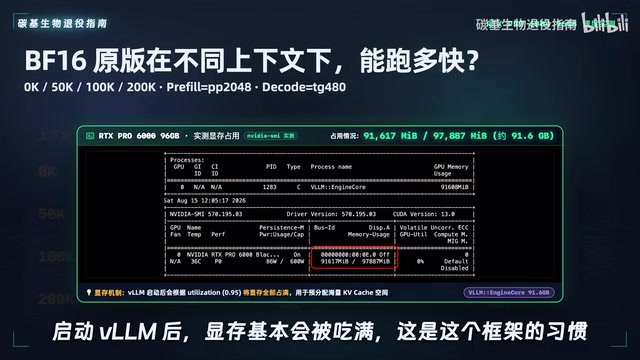
Even the ¥110,000 RTX Pro 6000 (96GB) didn't run much faster than consumer setups under the vLLM framework — because vLLM prioritizes throughput over single-request speed.
Real-World Performance: Earning a Seat at the Big Table
The evaluation followed the creator's established "local LLM head-to-head" benchmark format, with qualifying rounds and finals.
Qualifying Round: On Par with the Previous Generation
Using Q4KM quantization on the dual V100, Qwen3.8 and Qwen3.6 27B scored identically across all three test categories — both totaling 27 points. The dense model's long-standing issue of "code feeling too Chinese-flavored" remains.
Finals: A Dominant First-Place Finish
The real highlight came in the finals. Running Q5 quantization with Q8 KV on the 5090 across all final test categories, Qwen3.8-27B claimed first place by a wide margin: perfect scores on three categories, 42 points on the most demanding long-horizon task, and a total score 13 points ahead of second place — all while running a lower quantization level than competing models.
Full-Precision Validation: Approaching Top-Tier Online Models
To quantify the capability loss from quantization, the creator ran the official BF16 full-precision model with full-precision KV and vLLM on the 96GB workstation. The result: 76 points, with 46 points on the full-stack application task. This score surpasses GPT-5.5 and sits just 2 points below GPT-5.6.
Compared to the quantized version, the main issues in quantized runs were full-screen code bugs and minor layout imperfections. The full-precision version had zero bugs and handled details carefully. Both versions had similar frontend styling — and notably more modern than DeepSeek — suggesting Alibaba paid particular attention to frontend output during training. This confirms a key insight: quantized vLLM does meaningfully reduce capability, and you should validate with the official full-precision model when resources allow.
Conclusion: Qwen3.8-27B Is Powerful, but the Price Is Real
Qwen3.8-27B delivers genuine capability on complex coding tasks, pushing the local deployment ceiling up to the level of online frontier models. But the conclusion is also grounded in reality: running the full-precision version at home requires serious hardware investment, and even a six-figure GPU card won't make a dense model run particularly fast.
For everyday users, the recommendation is clear — use the highest quantization level you can actually afford, because the only reason to choose a 27B model is its edge on complex tasks, and the harder you quantize it, the more of that edge you lose. This open-source release is genuinely impressive, but the hardware and speed barriers to local deployment remain unavoidable real-world considerations.
Related articles

LLM Application Development: A High-Paying Career Guide for Ordinary People
LLM application development offers fresh graduates up to 35K/month, with SP offers reaching 600K. This article explains the core skills, how to break in, and how ordinary people can seize AI opportunities through learning by doing.

Say Goodbye to AI Influencer Faces: A Complete Guide to Creating Visual Assets for AI Comic Dramas from Scratch
Bilibili creator shares a full workflow for zero-basics AI comic drama visual assets: use Doubao Work skills with script-first, visual references, and real-person texture to escape AI influencer faces, then lock character and scene consistency with asset sheet layouts, weapon detail images, scene nine-grids, and cinematic color palettes.

The AI Production Pipeline Behind Great Videos: From Research to Agent Validation
AI video production isn't just a model race. This article breaks down a transferable four-step pipeline: researching professional workflows, organizing a skill checklist, configuring agents, and experimental validation—and explains how general-purpose LLMs like DeepSeek can replace paid tools to run the entire process.