Running a 284B Model on 64GB of RAM? The Truth Behind llama-modchip
llama-modchip claims a 284B model runs on 64GB RAM without a GPU, but community reproduction has failed—caution is advised for production.
The llama-modchip project claims the DeepSeek-V4-Flash 284B model can run on a machine with no GPU and only 64GB of RAM, drawing community attention. Its approach is based on memory mapping and on-demand scheduling of a Mixture of Experts (MoE), keeping only currently activated expert weights in memory while loading the rest via page swapping. However, the vendor-reported speed data has not been reproduced by multiple attempters on Hacker News, with clear gaps in actual latency and throughput—likely because the test scenario had high expert hit rates while actual usage has more random routing, causing frequent paging. No authoritative third-party benchmark exists yet. The article concludes that this solution is better suited to offline environments or research exploration, that production scenarios should still prioritize hosted models, and that caution is warranted until an independent benchmark appears.
Starting with a Repository Claim
The llama-modchip project recently claimed that the DeepSeekAd-V4-Flash 284B model can run on machines with no GPU and only 64GB of RAM. This claim quickly sparked discussion in the community—a 284B-parameter model typically requires far more than 64GB of VRAM or RAM, and performing inference purely on CPU and memory sounds like writing "impossible" into the README.
The approach described in the repository is not traditional quantization, but rather a refactoring around memory mapping and expert routing, claiming that under specific configurations the model can "fit and run." But it must be made clear: what's written in the repository is a feasibility description, not an independently reproduced performance benchmark. The speed data comes from the vendor side, not from third-party testing.
What the Repository Actually Says
llama-modchip's core claims center on two points: first, that the 284B model can be loaded in a 64GB memory environment; second, that usable throughput can be achieved through a modified inference path. The repository provides configuration instructions and running guidance, but its definition of "usable" is relatively broad—it doesn't provide a unified latency and throughput benchmark, nor does it disclose a complete controlled experimental environment.
This means the repository's claim is closer to "such a path exists" rather than "this path performs well in general scenarios." For developers who want to directly replicate it, the repository's information is enough to start an attempt, but not enough to predict the outcome. This is also the root of the subsequent controversy.
The Vendor-Reported Speed, and What Hacker News Couldn't Reproduce
The vendor-reported speed data is one of the focal points of this round of discussion. According to the repository side, the solution can achieve acceptable speed levels on the target hardware. But the discussion on Hacker News presents another side: multiple attempters said they could not reproduce the claimed performance, and the actual latency and throughput showed a clear gap from the vendor's description.
Community feedback diverges mainly on a few points: whether model loading truly stays within the 64GB boundary, whether inference triggers massive memory paging, and how different hardware configurations affect the results. These variables are not fully disclosed in the vendor report, leaving replicators facing a black box where "different parameters, different results."
One more note: there is currently no authoritative third-party systematic benchmark of the llama-modchip solution. Feedback on Hacker News is individual experience and cannot be equated with a conclusion, but it is enough to show that the vendor's speed data lacks universality.
Reproducibility of benchmarks: In system performance evaluation, reproducibility requires that the experimental environment, load characteristics, and measurement methods be fully disclosed so that third parties can verify results under the same conditions. If the vendor's speed data lacks these details, replicators can only guess at the configuration, leading to divergent results. Feedback on Hacker News reflects exactly this: different hardware (CPU model, memory bandwidth, disk type) and different input sequences all affect expert routing and paging behavior, producing vastly different latency and throughput. Therefore, until an independent benchmark appears, vendor data can only be regarded as a reference under specific conditions, not as a universal performance promise.
Why Running 284B on 64GB Is So Difficult
The weight volume of a 284B-parameter model far exceeds 64GB—this is a fundamental constraint that cannot be avoided. Any solution that makes it "fit" into 64GB essentially requires trade-offs in precision, sparsification, or on-demand loading. llama-modchip's approach most likely involves on-demand scheduling under a mixture-of-experts structure—keeping only the currently needed expert weights resident in memory while the rest stay on disk or are paged in.
The cost of this design is obvious: once the inference path frequently crosses expert boundaries, data movement between memory and storage becomes the bottleneck, and latency rises accordingly. The reason the vendor-reported speed is hard to reproduce is likely that the test scenario happened to fall on paths with high expert hit rates, while actual community usage is closer to a random distribution.
Mixture of Experts (MoE) and expert routing: Mixture of Experts is a sparsely activated architecture in which the model contains multiple "expert" sub-networks, but only a few are activated in each forward pass. A router network decides which experts to assign tokens to based on the input. This allows the total parameter count to be large while the computation per inference is relatively small. However, the weights of all experts still need to be stored, so memory usage is not reduced. llama-modchip's approach is precisely to exploit MoE's sparsity by keeping only the currently activated expert weights in memory and storing the rest on disk, loading them on demand. This on-demand scheduling depends on the locality of expert routing—if the experts corresponding to the input are concentrated, paging overhead is small; otherwise, frequent paging causes latency to spike.
Memory mapping (mmap) and page swapping: Memory mapping is a technique that maps a file or device into a process's address space, allowing a program to access files on disk as if they were memory. When an accessed page is not in physical memory, a page fault is triggered, and the operating system loads the corresponding page from disk into memory. llama-modchip may use mmap to map model weight files into memory, thereby breaking through physical memory limits. But frequent page faults cause massive disk I/O, becoming a performance bottleneck. Especially when expert routing is highly random, the number of page swaps surges and latency rises significantly. This explains why the vendor-reported speed is hard to reproduce in general scenarios—the test may have used inputs with high expert hit rates, while actual usage has a more random routing distribution.
When to Use a Hosted Model
If your goal is a stable and predictable inference service, a hosted model is almost the default answer. DeepSeek-V4-Flash or other models of the same tier in the cloud don't require you to worry about memory boundaries, expert scheduling, and paging strategies—latency and throughput are guaranteed by the service provider.
Solutions like llama-modchip have value in a narrower set of scenarios: offline environments, data that cannot leave the internal network, or purely research purposes to validate a technical path. For individual developers doing experiments, running a 284B model on 64GB of RAM is a meaningful exploration; but for production workloads, pinning hopes on an unverified CPU inference solution carries high risks and maintenance costs.
A Rational View of "Can Run" vs. "Works Well"
llama-modchip's claim opens a door, but the path behind it is not smooth. The repository describes feasibility, the vendor reports speed under specific conditions, and Hacker News feedback shows reproduction difficulties—only together do the three form a complete picture.
For such projects, a reasonable expectation is: it can serve as a research starting point to help you understand the scheduling boundaries of large models on constrained hardware; but it is not yet a solution you can entrust production traffic to. Until an independent benchmark appears, staying cautious is the safer choice.
One-line Summary
llama-modchip claims a 284B model can run on 64GB of RAM without a GPU, but community reproduction has failed—caution is advised for production.
Related articles
Codex and AI Coding Agents in Practice: A Complete Guide from Prompts to MCP
A Codex-centered guide to agentic coding: Task-Context-Output prompts, AGENTS.md project memory, plan mode, skills, characterization vs. spec tests, permissions and config.toml, MCP tool calls, plus secrets safety and context management.
GPT-6 Security Model and the AI Attack-Defense Escalation: This Week in AI
This week in AI: OpenAI's GPT-6 Saber found 948 Linux kernel root-escalation paths; Cursor deploys full apps from one sentence; Binance details a social engineering attack; C++26 fails ISO vote.
KIKUmap: Manage Your Claude and ChatGPT Conversations with Mind Maps
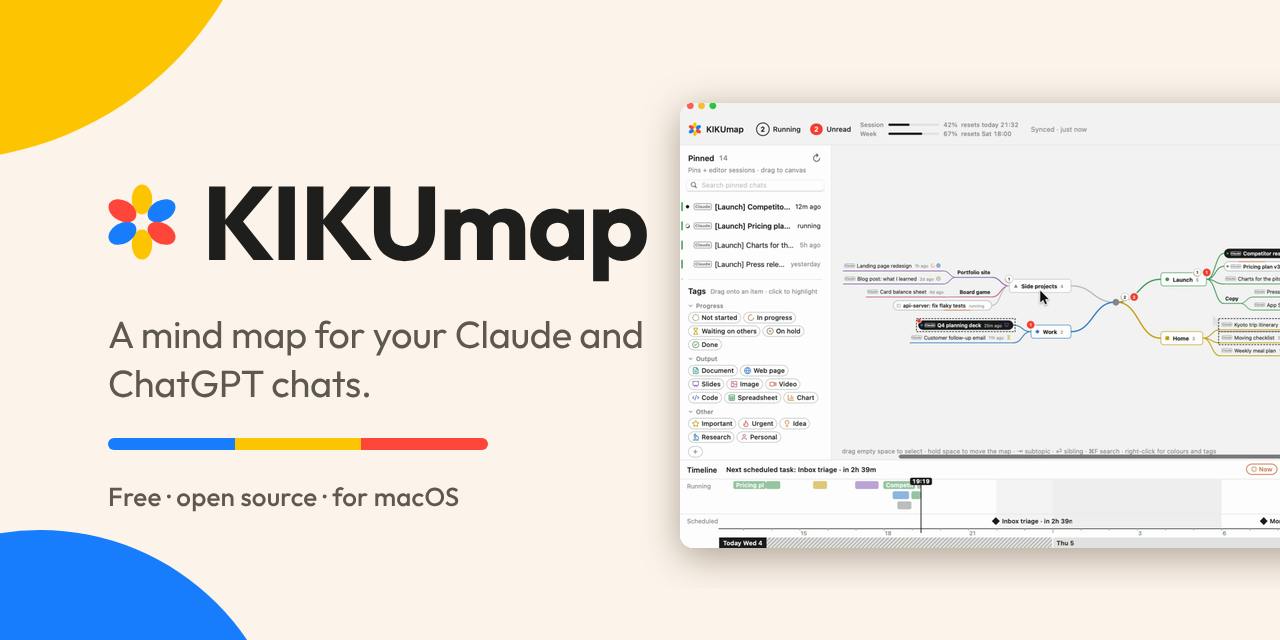
KIKUmap is a macOS menu bar app that visualizes Claude and ChatGPT conversations as mind maps with real-time status. Free and open source.