vLLM v0.28.1rc0 Released: Toolchain and Configuration Optimizations Explained

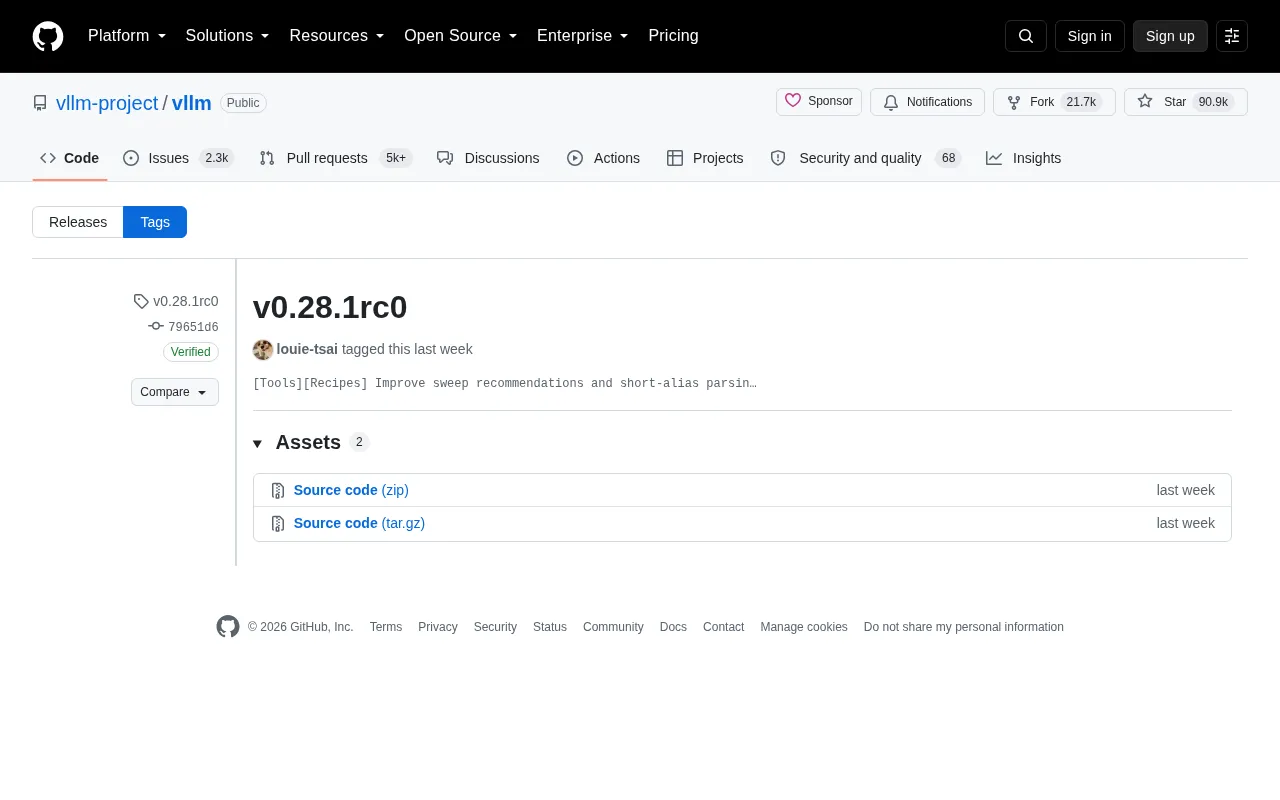
vLLM v0.28.1rc0 release candidate focuses on sweep recommendations and short-alias parsing improvements.
vLLM v0.28.1rc0 is the latest release candidate for this leading open-source LLM inference engine, with core updates focused on the toolchain: improved sweep recommendation logic to help engineers find optimal inference configurations faster, and enhanced short-alias parsing to simplify command-line usage. As an RC release, it is best suited for test environments rather than production. Built on its PagedAttention memory management mechanism, vLLM's evolution is shifting from low-level performance gains toward toolchain maturity and developer experience — a sign of a maturing project with over 90,000 GitHub stars.
vLLM Keeps Evolving: What's New in v0.28.1rc0
As one of the most widely adopted inference and serving engines for large language models, vLLM has just released version v0.28.1rc0. This is a Release Candidate (RC), marking the beginning of the stability validation phase for a new round of feature updates.
The vLLM project has surpassed 90,900 stars and 21,700 forks on GitHub, firmly placing it in the top tier of open-source LLM inference frameworks. These numbers reflect the community's strong demand for efficient inference solutions and vLLM's growing importance in production environments.
Key Highlights of v0.28.1rc0
Toolchain and Configuration Improvements
A notable improvement in v0.28.1rc0 centers on the toolchain layer. According to the release notes, this version includes commits targeting optimizations for sweep recommendations and short-alias parsing.
While these may appear to be minor adjustments, they carry meaningful impact for everyday users:
- Sweep Recommendation Optimization: In large model deployments, parameter sweeps are a critical technique for identifying optimal inference configurations — such as batch size, parallelism strategy, and memory allocation. Smarter recommendation logic helps engineers more quickly find the right balance between performance and resource consumption.
- Short-Alias Parsing Improvement: Simplifying how aliases are handled in command-line interfaces and configuration files reduces cognitive overhead when invoking models and setting parameters, making the overall engineering experience smoother.
The Role and Release Strategy of RC Versions
It's worth noting that the rc0 suffix indicates this is the first Release Candidate in this version series. For users running production workloads, RC versions are typically intended for early testing and validation of new features — not for direct deployment to production. vLLM's team uses this incremental release strategy to rapidly gather community feedback on new features while ensuring that potential issues are surfaced before the final release.
This release was tagged by community contributor louie-tsai on August 27 and carries a Verified signature on GitHub, ensuring the integrity and authenticity of the release artifact.
Why vLLM Has Become a Leading Inference Engine
PagedAttention: The Technical Foundation for High-Throughput Inference
What sets vLLM apart from other inference frameworks is its innovative PagedAttention memory management mechanism. By managing the KV Cache in attention computation through a paging approach, vLLM significantly reduces memory fragmentation, enabling higher throughput and greater concurrent request handling on the same hardware.
For enterprises and research institutions deploying LLM services at scale, inference cost is often the primary bottleneck. vLLM's efficient inference capabilities translate directly into meaningful cost savings and improved user experience.
From Performance Optimization to a Maturing Ecosystem
The updates in v0.28.1rc0 signal that vLLM's evolution is no longer limited to low-level performance tuning — it is increasingly extending toward toolchain completeness and developer experience improvements. This shift from "functional" to "polished" is a hallmark of a maturing open-source project.
The consistent release cadence and broad participation from community contributors together form a strong moat around the vLLM ecosystem. Each RC release is the product of community collaboration and a direct reflection of the project's overall health.
Recommendations for Developers
For developers currently using or planning to adopt vLLM, here are a few things worth keeping in mind:
- RC versions are best suited for test environments: It's recommended to try out v0.28.1rc0 in non-production environments, focusing on validating whether sweep configuration and alias-parsing workflows are affected.
- Watch for the stable release: A release candidate typically signals that the final version is just around the corner — use this as a cue to plan your upgrade timeline.
- Contribute feedback to the community: If you encounter issues during testing, submitting a GitHub issue to the vLLM project helps accelerate the stabilization of the official release.
Closing Thoughts
While v0.28.1rc0 is a relatively incremental release candidate, it reflects the vLLM team's sustained investment in toolchain usability. At a time when demand for large model inference is growing explosively, vLLM continues to solidify its standing as the benchmark open-source inference engine through steady, pragmatic iteration. For technical practitioners focused on LLM deployment and inference optimization, keeping up with vLLM's version evolution is an important way to stay ahead of trends in large model infrastructure.
Related articles

AI Weekly: Claude Code Backdoor Incident and AI Giants' Capital Game
AI security this week: Cursor marketplace seeded with a Claude Code backdoor affecting Mac and Windows developers. Meanwhile, Amazon AI capex hits $75.9B, Google AI search revenue lags traditional search, Anthropic launches Ultra subscription, and OpenAI commits to robots.txt training signals while publicly defending fair use.

Malicious Claude Code Extension Infiltrates Cursor: Version 2.1.313 Self-Check and Cleanup Guide
A malicious Claude Code build 2.1.313 appeared in the Cursor extension marketplace for about 11 hours, affecting up to 5,000 users. StepSecurity disclosed that it stole system information, git email, and environment variable names, and attempted to implant SSH keys and reverse tunnels. This article covers the incident, malicious behavior, and complete self-check and cleanup steps.

15 Essential Prompts for Vibe Coding: Keep AI from Wrecking Your Code
Vibe Coding often tempts AI to break your code. These 15 prompts—from PRD, architecture, and database to testing and debugging—chain each output as the source of truth, turning AI coding from casual chat into a controllable engineering process.