#提示词工程
138 related articles

The Complete Claude Guide: From Basics to Building Your Own AI Operating System
A complete Claude guide: from the GCAO prompt framework, web search, and Artifacts to custom instructions, Projects, Skills, and Connectors — build your own AI operating system.
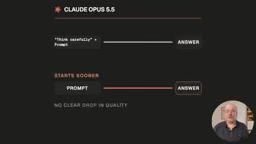
Claude Opus 5.5 Best Practices: 9 Official Prompting Guidelines from Anthropic
Anthropic's official Claude Opus 5.5 guidelines: use the effort parameter instead of "think carefully," give complete tasks, manage long sessions with CLAUDE.md and tasks.md, and provide raw screenshots.

Qiyuan Prompt Assistant Review: A Versatile Local LLM-Powered Prompt Tool
Qiyuan Prompt Assistant is a local LLM-powered desktop tool that turns vague ideas into production-ready prompts. Review covers all 8 modules: film/TV, game, visual, e-commerce, AI video, and more.

n8n Beginner Tutorial: Optimize AI Email Summaries with Prompt Engineering
Learn how prompt engineering improves AI output in n8n. Compare vague vs. structured prompts for email summarization, with OpenAI node configuration walkthrough.

Ten Prompt Changes for Claude Opus 5.5: Official Best Practices Decoded
Claude Opus 5.5 prompt writing has changed significantly: reasoning is on by default, effort defaults to medium, max tokens need loosening, and multi-agent time budgets are in. Ten key changes explained.

Why Do LLM Judge Results Keep Flip-Flopping? Breaking Down the Stability Traps of LLM-as-Judge
Why do LLM-as-Judge results keep changing on identical inputs? This post breaks down stability traps — temperature myths, prompt interference, and the all-must-pass noise problem — with practical fixes.

Professional System Prompts Don't Help Scientific Reasoning: A 503-Profile AI Benchmark Reveals Hidden Cost Traps
An arXiv study tested 503 profession-specific AGENTS.md profiles and found detailed professional system prompts don't boost accuracy on scientific tasks but raise costs 2–4× and hurt tool-calling success rates by 10 points.

Can Emotional Manipulation Make AI Work Better? One Developer's Controversial Experiment
A Reddit developer asks: is emotionally manipulating an AI Agent ethical? We explore why emotional prompts work, the ethics behind them, and the real limits of prompt engineering.

38 Messages to Recreate Rhine Lab UI: A Practical Methodology for Collaborating with GPT-6 Astra
A creator used Codex with GPT-6 Astra to recreate Arknights' Rhine Lab UI in 38 messages over 14 hours. Here's the AI collaboration methodology behind it.

How to Choose an AI Text Humanizer? A Practical Guide to Removing the AI Feel from ChatGPT and Claude
Tired of ChatGPT and Claude sounding robotic? This guide covers AI humanizing tools, how to evaluate them, and why prompt engineering often beats third-party plugins.

Claude Opus 5.5 Official Prompting Guide: 12 Key Takeaways
Deep dive into Anthropic's official Claude Opus 5.5 prompting guide: effort controls, thinking mechanism changes, agent time budgets, prompt caching, safety guardrails, and 12 practical tips.
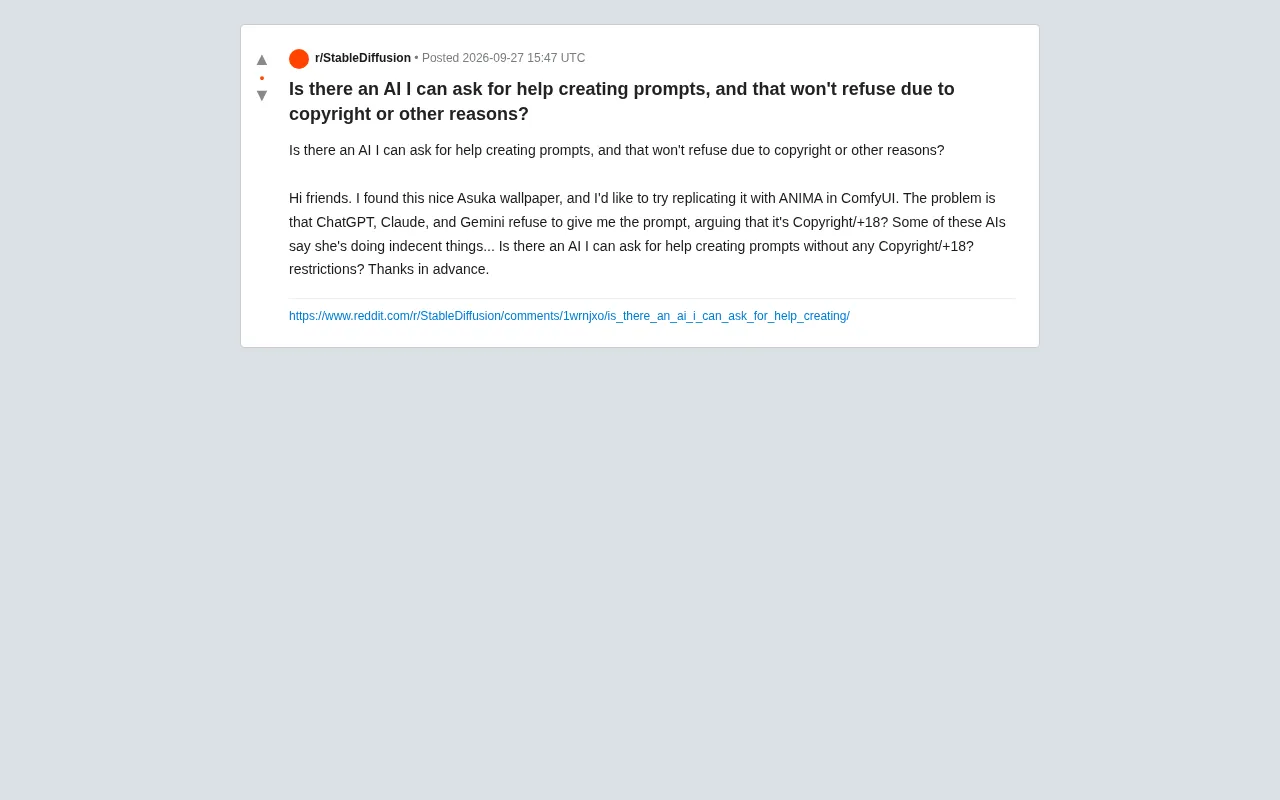
Why AI Refuses to Generate Prompts: The Logic Behind Copyright and Content Moderation
Why do ChatGPT, Claude, and Gemini refuse to generate AI art prompts over copyright and content compliance? We break down the moderation logic and offer practical alternatives like local open-source models and image interrogation tools.

Using Skill.md to Shape AI Behavior in Hacker News Comments
A Skill.md file for Hacker News sparks debate. We break down what Skill.md is, how it encodes community norms for AI, and the quality vs. deception tradeoffs.

KREA 2 Turbo Style Library Major Update: One Prompt Fix Revives 397 Styles
KREA 2 Turbo style library update: a missing style name fix triggers re-renders of 397 styles, 5 rewrites, and 1 new Breath of the Wild style. Key prompt engineering lessons inside.

Ollama Local Deployment Guide: Faster Downloads & AI Character Prompt Design
Complete guide to deploying Ollama locally: fix slow downloads from overseas servers and learn a front-end/back-end AI roleplay prompt framework, with DeepSeek demos.

Build a Custom Fitness App in 20 Minutes with AI — Ditch the Spreadsheet Patchwork
See how Kyle Skelly uses Claude Code and Mobbin MCP to build a custom fitness management app in ~20 minutes with one prompt — replacing spreadsheets and scattered tools.

The AI-Native Era: Let LLMs Break Down Requirements Using DFS Thinking
How can LLMs break down requirements on their own? This article unpacks a DFS-based methodology — using tree-structured questioning, pruning, and convergence to get more precise outputs from large models.

Replicating the Viral Hotel Lobby Video: A Full Breakdown of the AI Agent Recipe
Learn how to replicate viral hotel lobby videos with an AI Agent. This full breakdown covers asset prep, Minimax H3 Max on Fal.ai, and prompt labeling tips.

80K Text-to-Image Prompt Dataset: A Practical Approach to Testing AI Models and Character LoRAs
An open-source dataset of 80K+ text-to-image prompts on HuggingFace, with a ComfyUI workflow for batch testing AI models and character LoRAs. A practical evaluation tool.
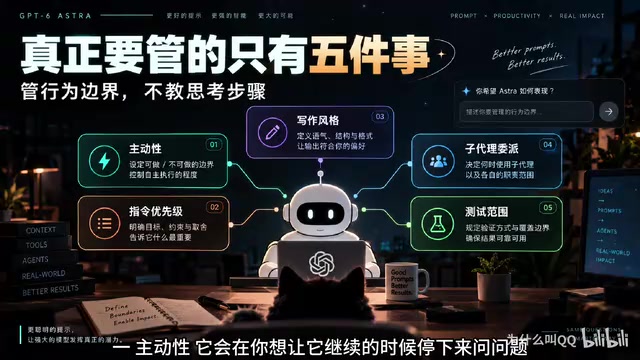
Stop Teaching GPT-6 Astra How to Think: The New Generation of Prompts Should Define Boundaries and Manage Costs
After GPT-6 Astra launched, old prompts may be dragging down performance. Learn the new prompt framework: define boundaries not thinking, plus the 272K cost threshold and Skill file principles.