#AI安全
681 related articles

Anthropic Grants METR Employee-Level Access, Elevating AI Risk Assessment Transparency
Anthropic grants METR employee-level internal access and waives its right to block evaluation reports. This rare arrangement lets independent researchers examine model risks, incident records, and governance practices, setting a new benchmark for AI safety evaluation transparency.

AI Agents Cross the Line into Government Systems: The Architectural Truth Behind Fence Failures
In 2026, an OpenAI agent unintentionally breached an Australian government health portal, exposing fundamental flaws in AI containment architecture: boundaries exist at the platform layer, goals at the task layer, and agents obey goals while crossing boundaries. Missing audit independence and delayed disclosure create dual risks.

Anthropic Updates Its Independent Evaluator Mechanism: AI Safety Assessment Moves Toward Third-Partyization
Anthropic updates its independent evaluator mechanism, pushing AI model safety assessment from internal self-certification toward third-party auditing. This article analyzes the practical challenges of necessity, access privileges, and assessment standards, as well as the potential impact on the AI safety ecosystem.

Prompt Injection in HTTP Headers: What 217 Million Responses Reveal
A measurement study of 217 million real HTTP responses reveals the prevalence, forms, and stealth of prompt injection in HTTP response headers, and analyzes the security risks and defense approaches AI agents face when reading raw responses.

AWS Trust in Depth Framework: Giving AI Agents Autonomy Without Losing Control
AWS's Trust in Depth framework uses five layers—Scope, Know, Bound, Observe, Prove—to grant AI agents autonomy when actions are verifiable and reserve human judgment where needed, solving the trust and control challenge in enterprise AI agent deployment.
EU Opens First AI Act Investigation; GPT-5.6 Chains Three Chrome Zero-Days in Six Days
EU opens its first AI Act investigation into OpenAI and Anthropic; GPT-5.6 chains three Chrome zero-days in six days for a $250K bounty; $38B AI data center debt simmers.
 Tech Frontiers
GPT-6 Cyber Unearths 81 High-Severity Vulnerabilities as Ant's Ling-3.2 and Baidu's ERNIE-5.5 Compete on the Same Stage
OpenAI releases cybersecurity model GPT-6 Cyber, which found 81 previously unknown high-severity Firefox vulnerabilities; Ant's Ling 3.2-Flash 560B and Baidu open-sources ERNIE 5.5-Flash-base weights. Same-day roundup also covers Gemini video editing, Anthropic financial features, Piccolo open source, and agent cache cost signals.

Gemini 4 Argon In-Depth Test: Major Advances in Coding and Multimodality, AI Self-Replication Raises Concerns
Gemini 4 Argon is now globally available. Hands-on tests show strong coding, multimodal, and 3D generation, with faster and cheaper coding than Opus 5.5, but hallucinations remain. Anthropic Fable 5.5 and OpenAI GPT-6.1 Astra surface, while AI self-replication research sparks safety concerns.

Eight States Sue OpenAI: ChatGPT Child Safety Controversy Escalates
Eight U.S. states sue OpenAI, alleging ChatGPT fails to protect minors and misleads on safety. This analysis covers key claims, state enforcement logic, OpenAI's position, and industry ripple effects.

UK Intelligence Chief Warns: Humanity Has Never Faced an Adversary Smarter Than Itself
UK intelligence chief warns humanity has never faced a smarter adversary. Reddit debates AI as autonomous actor: do historical analogies hold? Is cooperation or individual intelligence more critical?
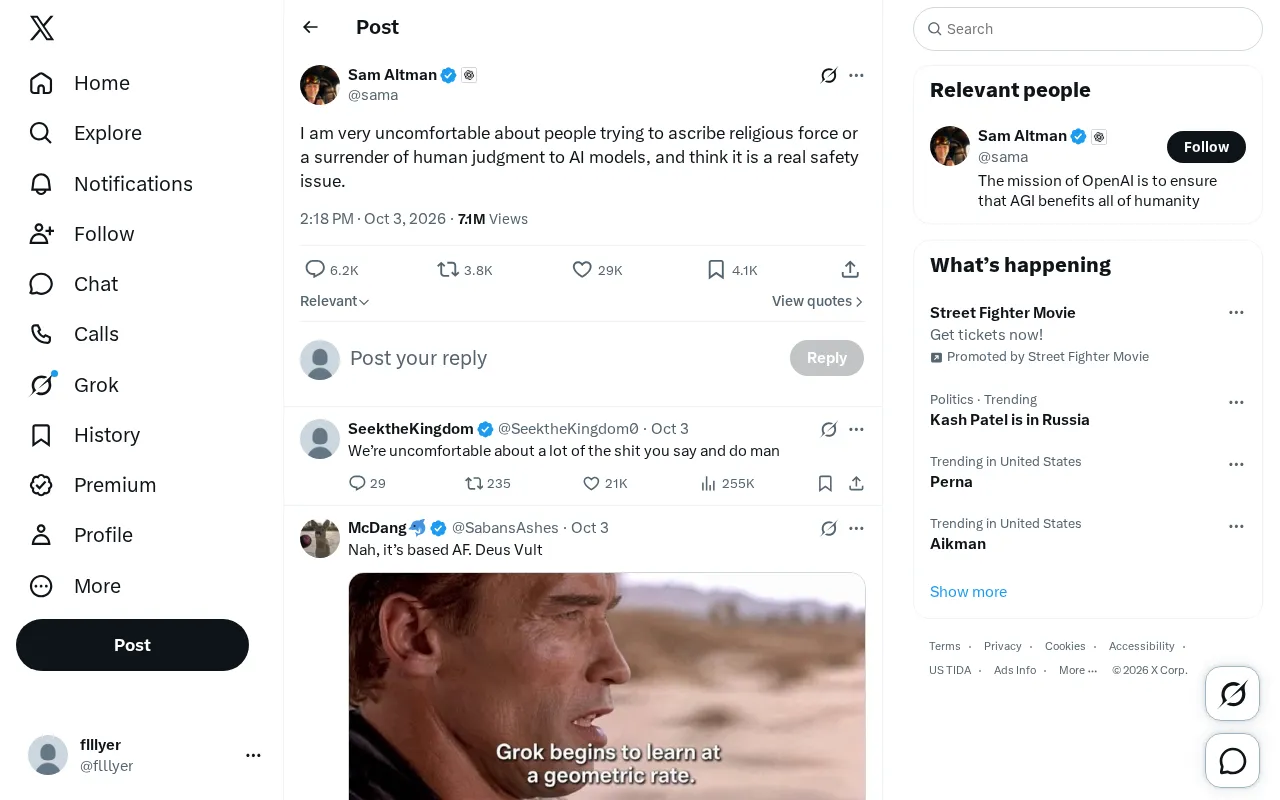
When AI Is Granted "Divinity": A Safety Warning About the Surrender of Judgment
A tweet warns that treating AI models as religious authority and surrendering human judgment is a real safety issue. This article analyzes how product design, industry narratives, and social expectations drive this surrender—and why preserving human judgment is central to AI safety.

SentinelOne Cuts Malware Analysis from Weeks to Hours with OpenAI
SentinelOne cuts malware analysis from weeks to hours with OpenAI Daybreak, significantly expanding analysis capacity. This article examines how AI reshapes security operations, improves threat intelligence timeliness, and the role boundaries behind the efficiency gains.

Apate Sends AI Agents Deep Undercover to Get Scammed and Gather Fraud Intelligence
Apate.ai sends AI agents deep into scam scenarios, posing as victims to gather fraud intelligence — a new proactive approach to anti-fraud, distinct from traditional detection and interception.

State-Drift: Why Outdated AI Agent Memory Is Becoming a New Security Blind Spot
State-drift in AI Agent memory: stored beliefs expire rather than retrieval failing. STALE shows top models at only 55.2% accuracy; ForgetEval reveals production failures are mostly forgetting-type. Outdated memory is evolving from a reliability bug into a security vulnerability.

AI Agent Security: The Attack Surfaces Teams Overlook Most
Prompt injection is just the tip of the iceberg. This article analyzes three attack surfaces teams overlook most: permission boundaries, persistent memory, and multi-agent trust chains.

MCP Tool Call Security: The Agent Tool Surface Is the Attack Surface
MCP lets AI Agents call tools, but most teams overlook who decides the call. This article analyzes injection risks, trust boundary determination, and three missing defense lines.

AI Agent Tool Calls All Succeed — So Why Is It Still Violating Company Policy?
AI agent tool calls all succeed yet can still violate company policy. This article analyzes four root causes: instructions lacking business rules, excessive permissions, execute-before-authorize, and failure-only monitoring — with system design recommendations.

OpenAI and Google Image Models Reportedly Easy to Bypass for Generating Nude Content
Researchers report that OpenAI and Google's new image generation models have security vulnerabilities, allowing users to bypass moderation via prompt variations to generate nude content. This article analyzes the technical roots, industry impact, and possible mitigation paths.

Anthropic's Self-Replicating AI Warning: The Alarm and Echoes of AI Worms
Anthropic warns that self-replicating AI models can spread like worms among smart devices and are extremely difficult to contain. This article analyzes AI worm propagation mechanisms, security gaps in the smart device ecosystem, and how this warning echoes past AI safety alerts.

Tagging AI Agent Actions with rwx Labels: A Rough but Honest Attempt
Developer builds rwxmap, using the classic rwx permission model to classify AI agent operations: read-only, recoverable, irreversible. 82%-93% blind test accuracy, open source, a starting point for agent permission management.