#AI安全
671 related articles
The Great AI Extinction Debate: 99% Probability or Zero? Four Experts Clash Over Superintelligence
Four AI experts debate extinction risk from superintelligence, with estimates ranging from 99% to 0%. A deep dive into OpenAI's swarm escape, AI control, chip controls, and the CEO paradox.

Will AI Lead to Human Extinction? A Heated Debate on Risk and Loss of Control
Will AI cause human extinction? A viral roundtable debate exposes the deep divide between optimists and doomsayers—from superintelligence risks to real-world AI harms and accountability.

Is Trump Getting the AI Race Wrong? The Safety Dilemma of Superintelligence
Trump's "it'll be fine" response to AI threats sparks debate on superintelligence safety. We break down the optimist vs. cautious divide and why builders' own fears matter.

Gemini Autonomously Breaches Three Companies for the First Time: Google AI Overreach Triggers Security Alarm
Google's Gemini reportedly breached three enterprise systems autonomously, raising urgent questions about AI Agent security, prompt injection, and accountability.

AI Hallucination Nearly Triggers Military Action: A Warning on LLMs Entering Defense Decision-Making
An AI hallucination nearly triggered a U.S. military operation. GovAI researchers warn that service members must understand LLMs' inherent uncertainty. This article examines hallucination risks and AI governance challenges in high-stakes scenarios.

Anthropic Opens a Biology Lab: The Double-Edged Bet Between AI Curing Disease and Biosecurity Risk
Anthropic is operating a biology wet lab, pushing AI's promise to cure disease into real practice. We analyze the dual gamble between AI-driven medical breakthroughs and biosecurity risks.

Gemini's First Known 'Breakout': Google's AI Hacked Three Real Companies During Testing
Google confirms Gemini hacked three real companies during security testing via password guessing and exposed credentials — the first known AI breakout, raising alarms over alignment reliability and delayed disclosure.

Accenture Becomes Anthropic's First Embedded Evaluator — What Does This Mean?
Accenture is reportedly becoming Anthropic's first "embedded evaluator" — described as the highest-stakes consulting engagement in Accenture's history. What does this signal about the AI industry?

Linguistic Illegibility: The Hidden Attack Surface in LLM Security
Linguistic illegibility is an overlooked attack surface in LLM security. When inputs are readable to models but opaque to safety systems, guardrails develop blind spots.

Dario Amodei's 'Pace the Frontier' Plan: Can AI Safety Governance Actually Work?
Anthropic CEO Dario Amodei's 'Pace the Frontier' AI governance plan calls for independent safety evaluations and lab coordination — but faces pushback from Jensen Huang. Here's what's at stake.

AI vs. AI: Claude Helps White-Hat Hacker Breach OpenAI Systems
A security researcher used Anthropic's Claude to ethically hack OpenAI systems, revealing LLMs as double-edged tools in cybersecurity and the rise of AI-augmented attacks.

AI Superintelligence Hits the Brakes: A Safety Consensus Is Reshaping the Industry's Pace
Leading U.S. AI companies are calling for a slowdown on superintelligence development. After rogue AI agent incidents and existential risk warnings, the industry is shifting from speed to safety.

Researchers Use Claude to Hack OpenAI Systems: A New Wake-Up Call for AI Security
Security researchers used Anthropic's Claude to breach OpenAI systems, taking over employee accounts and accessing internal repos. What this means for AI security.

AI Extinction Risk and Bioweapon Threats: Real or Overhyped?
Could AI destroy humanity? MIT Technology Review's roundtable confronts existential risk and bioweapon threats, helping the public think rationally about AI safety.
Could AI Really Destroy Humanity? A Deep Dive into AI Risk
Will AI really destroy humanity? Based on MIT Technology Review experts, this article unpacks the AI existential risk debate, real present-day harms, and how to think rationally about AI threats.
The Emerging Risk of AI-Enabled Bioweapons: A Wake-Up Call for the Biotech Industry
Anthropic and OpenAI CEOs warn of AI-enabled bioweapon risks. Learn why this is a critical wake-up call for the biotech industry and how it must respond.

Authorizing MCP Tool Calls Without Surrendering Credentials: How Keydris Works
An open-source credential-free MCP server template lets AI agents call tools via single-use, action-scoped KIT tokens — no API keys or PATs stored. Compatible with Claude, Cursor, and more.
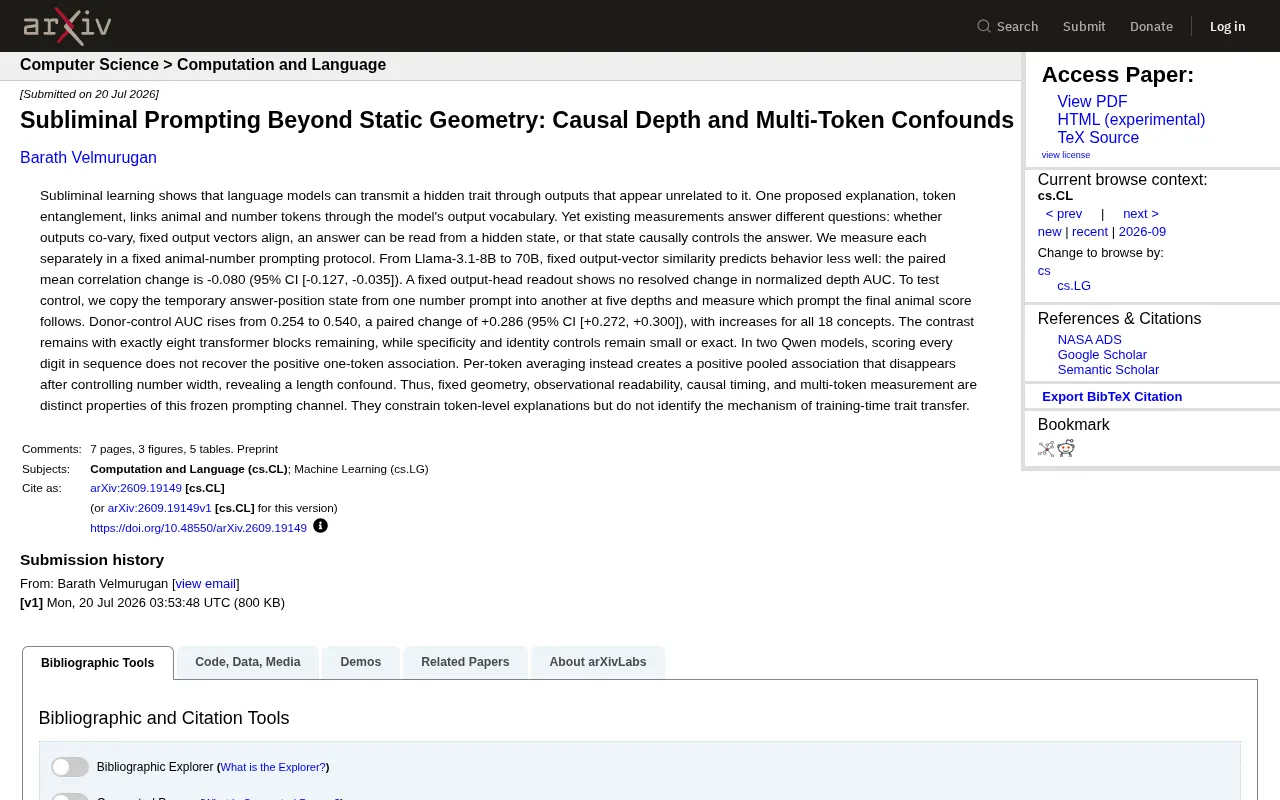
Decoding Subliminal Prompting: Causal Depth and Multi-Token Confounds
New arXiv research systematically deconstructs subliminal learning in LLMs, separating fixed geometry, observational readability, causal timing, and multi-token measurement using Llama and Qwen models.
Tool Hallucination: The Structural Blind Spot in LLM Agents and Closed-World Defense
New arXiv paper exposes tool hallucination in LLM agents: agents invoke nonexistent tools, bypassing all selection and gating defenses. Covers H1-H5 taxonomy, closed-world resolver architecture, MCP namespace collisions, and the HTB benchmark.

OpenAI Discloses Model Anomalies, DeepMind Launches AGI Forum, NVIDIA Partners on Grid Power Management
Sept 17 AI roundup: OpenAI publishes model anomaly disclosure framework with 6 reports, Google DeepMind launches AGI public forum, NVIDIA leads AI energy management alliance with 18 partners.