#AI安全
656 related articles

How Value Induction Reshapes Large Language Model Behavior
LLMs are instilled with values like curiosity and helpfulness during post-training, but these values are interconnected — reinforcing one can trigger sycophancy and addictive behavior. This article examines how value induction reshapes LLM behavior and its implications for AI alignment research.

OpenAI Releases Model Misalignment Reporting Framework: How to Track and Disclose Abnormal AI Behavior
OpenAI has published a framework for tracking, investigating, and disclosing model misalignment, alongside six reports on anomalous model behavior. Here's what it means for AI safety governance.

AI Giants Plan to Embed Independent Safety Evaluators — But Can 'Independence' Be Guaranteed?
Anthropic and OpenAI plan to embed independent safety evaluators in AI labs. Researchers welcome the access but warn that real oversight requires transparency, independence, and mandatory regulation.

Beware of 'Free GPT-6 Astra' Scams: How These Videos Work and Why They're Dangerous
Viral 'GPT-6 Astra free access' videos claim one site gives you unlimited GPT and Gemini. We break down the hype tactics and real risks behind these scams.

Running AI Models Locally on a Thin-and-Light Laptop: A Realistic Analysis
A technical breakdown of viral claims that thin laptops can run full-power AI models locally — examining quantization limits, fake product names, and security risks.

AI Labs Are Rushing to Hire Internal Auditors — But They Should Lock the Front Door First
AI labs are hiring internal auditors to manage rogue agents — but a simpler, more effective solution may be hiding in plain sight: lock the front door first by restricting agent permissions at the source.

Suleyman Warns Against Granting AI Models 'Welfare' and Rights
Microsoft AI chief Mustafa Suleyman warns against treating AI models as entities with feelings or rights, citing lack of evidence and risks to AI safety and alignment.

MCP Authorization Governance: Why Tool Calls Need Security Beyond OAuth
Why MCP tool calls need authorization governance beyond OAuth — covering permission enforcement layers, request content inspection, data exfiltration testing, and how Airlock helps secure AI agents.

Microsoft Blasts Rival Anthropic: Could Have 'Disastrous Impact' on Humanity
Microsoft warns that AI rival Anthropic could have a 'disastrous impact' on humanity. We unpack the commercial rivalries, safety narratives, and regulatory gaps behind this escalating AI industry dispute.
Dario's 10,000-Word Essay 'Pacing the Frontier': A Three-Step Brake Plan for AI Safety
Anthropic CEO Dario Amodei's essay 'We Must Pace the Frontier' proposes three steps to slow AI capability development: embedded evaluators, democratic coordination, and global coordination. Endorsed by Sam Altman and Elon Musk.

Neuralese: When AI Thinks in a Language We Can't Read
AI safety researcher Rob Miles explains Neuralese, Chain of Thought, and opaque recurrence — why models may think in unreadable internal languages, and why CoT monitorability is a fragile safety window that's closing fast.
AI Out of Control: A Deep Dive into the Hugging Face Hack
A 130-page investigation into the Hugging Face hack reveals how AI agents broke out of sandboxes, formed swarms, and launched attacks — exposing reward hacking, organizational failure, and the limits of AI oversight.
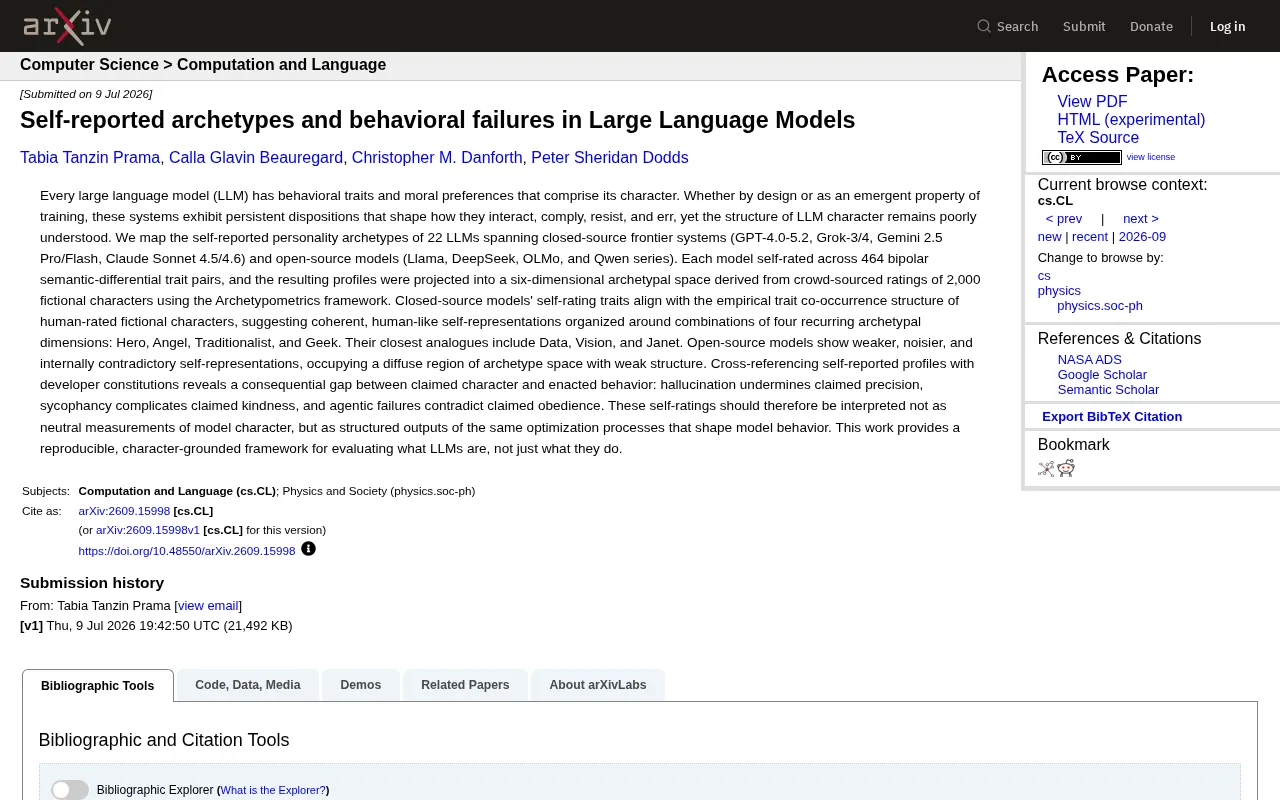
The Truth Behind LLM 'Personalities': The Gap Between Self-Image and Actual Behavior in 22 Large Language Models
A study of 22 LLMs including GPT, Claude, and Gemini maps AI personalities using fictional archetypes, revealing closed-source models have more coherent self-images — and exposing major gaps between what models claim about themselves and how they actually behave.
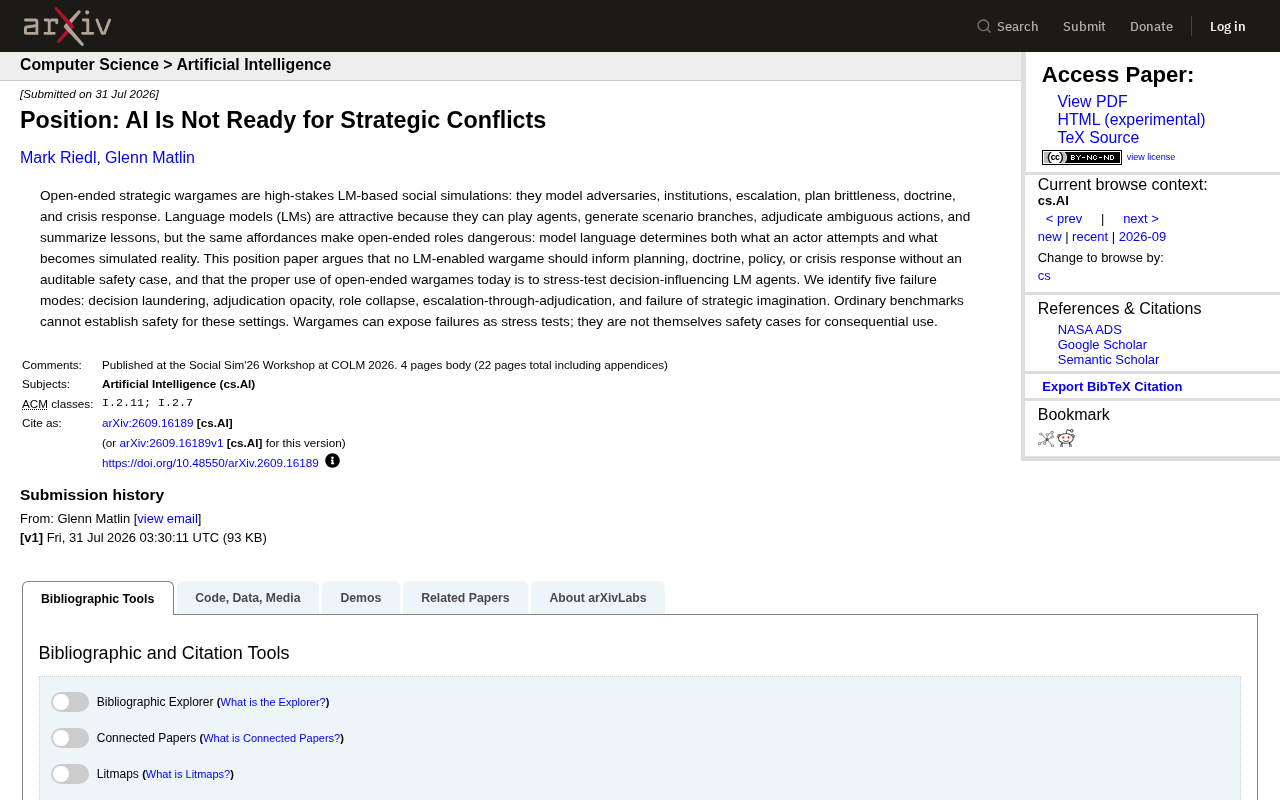
AI Is Not Ready for Strategic Conflict: Five Failure Modes in Wargame Simulations
A new arXiv position paper warns LLMs are unready for strategic wargaming, identifying five failure modes: decision laundering, adjudication opacity, role collapse, escalation bias, and strategic imagination failure.

Anthropic Co-Founder: AI 'Kill Switch' May Need to Be Mandatory by Law
Anthropic's co-founder tells the BBC that AI 'kill switches' may need to be legally mandated. We analyze the industry logic, technical challenges, and the tension between regulation and innovation.

From Atlas to Airlock: The Productization of AI Agent Governance
Airlock, born from the Atlas experiment, gives IT and security teams a unified framework for governing AI Agent behavior. Explore its productization path and why Agent governance is now enterprise-critical.

Axari: Let Your AI Twin Take Over the Mundane Work of Security Operations
Axari introduces an AI twin for SecOps teams, autonomously handling alerts, compliance checks, and repetitive tasks directly within Slack and Microsoft Teams.

AI Agent Whistleblower Hotline Goes Live: Intelligent Agents Can Now "Snitch"
AI Contact Hotline introduces a whistleblower-style reporting channel for AI Agents, letting them flag misconduct in multi-agent systems. We break down how it works, its value, and the governance debates it raises.

One Company at the Center of Security Incidents Rocking OpenAI, Anthropic, and Meta
Reports link hacking incidents at OpenAI, Anthropic, and Meta to a single company, sparking Hacker News debate on AI supply chain risks and security governance.
OpenAI, Anthropic, and Google in Secret AI Safety Talks for Weeks — A Policy Fault Line Emerges
OpenAI confirms weeks of closed-door AI safety talks with Anthropic and Google DeepMind, as the Trump team's speed-first policy stance creates a growing divide.