#LLM
128 related articles

Decoding OpenAI's Naming Logic: The Rules Behind Model Codenames and Version Numbers
OpenAI's Ted Sanders explains model naming rules: LLM performance is multidimensional but dominated by scale, with internal codenames Luna<Terra<Sol<Astra, and version numbers indicating release order, model relationships, and improvement magnitude.
Doom AI Doubles Its Score with an LLM Coach: A New Approach to Hierarchical Agent Design
A YouTube creator's experiment pairs a shoot-only Doom AI with an LLM coach in a hierarchical agent design, doubling its score. The LLM handles high-level tactics while GLiNER executes, offering key insights for AI application development.
How Does Memory Compression Mislead LLM Group Decisions? A New Benchmark Reveals Two Major Failure Modes
New benchmark CrossProfile reveals failure modes of memory compression in LLM group decisions: relevance-based selection introduces decoys, rarest-first is no better than random, and decision models exhibit social proof bias.

The "Claim Smoothing" Phenomenon in LLM Research Reports: Quantitative Evaluation with SmoothScore
LLM research agents exhibit "claim smoothing," drawing more confident conclusions than evidence supports. SmoothScore quantifies it, validated on 7 systems and 4 datasets.

Can Models Be Curious Too? New Research Quantifies Curiosity in LLM Questioning
A study introduces "model curiosity," building a taxonomy to distinguish curiosity-driven from ordinary questions. Analysis of four dialogue datasets finds curiosity questions account for only 17%-28% but correlate with more exploratory user responses; human studies show they are especially useful in advice, creativity, and research scenarios.

Open Source Community Bans AI Projects? R/open source's New Rules Spark Controversy
R/open source community's new rules ban solo projects and LLM-assisted projects, sparking debate on Hacker News. This article analyzes the open source governance anxiety, license risks, and real costs of one-size-fits-all rules behind the ban, exploring the boundaries of open source communities in the AI era.

Understanding vLLM and SGLang from First Principles: Deconstructing the Core Technologies of Inference Engines
Deconstructing vLLM and SGLang inference engines from first principles: how PagedAttention reduces memory fragmentation, how continuous batching boosts throughput, how RadixAttention and DSL scheduling optimize prefix reuse and complex generation workflows, plus selection advice.

The Geometry of Metaphor Representations in LLMs: Probeable and Steerable
Researchers use mechanistic interpretability to locate causal subspaces of metaphor representation in LLMs of various architectures and sizes, enabling probing and steering of metaphoricity in classification and generation tasks, revealing the geometric structure of LLM metaphor ability.
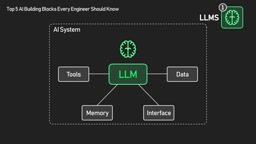
5 Core Modules Every AI Engineer Must Know
Explaining the five core modules every AI engineer must know: LLMs, embedding models, RAG, agent harnesses, and world models, and how they combine into real AI products like ChatGPT, recommendation systems, and self-driving cars.

Why Using LLMs for Confidence Scoring Is a Bad Idea
A Hacker News discussion shows why using LLMs for confidence scoring has fundamental flaws: models lack self-awareness, scores are poorly calibrated, and they create circular dependencies. This article analyzes the causes and offers more reliable alternatives like external verification and multi-model cross-validation.

Reddit Discussion: Have You Fully Handed Off the Most Boring Tasks to LLMs?
Reddit discussion: Which boring everyday tasks have you fully handed off to an LLM? This article analyzes users' behavioral shift from "assisted use" to "default outsourcing" and what it means for AI application development.

The Moon to Get Its First Large Language Model: Astrolab's FLIP Rover to Land in 2026
Astrolab's FLIP lunar rover is planned for launch in 2026, set to run large language models on the Moon for the first time, enabling localized AI computing, reducing communication latency dependence, and providing autonomous decision-making for future lunar bases and deep space exploration.

A Programming Obituary: How AI Coding Agents Took the Fun Out of Puzzle-Solving
Jeremy Scheff's "Programming Obituary" sparks debate: AI coding agents are changing what programming means and taking away the joy of puzzle-solving.

62 Lines of Bash Builds an AI Agent: How the Minimal Harness Works
Build an AI Agent from scratch with a 62-line Bash script: from a single LLM call to a chat loop to a coding Agent with bash tool calling. Plus a live Tetris test.
Load-Bearing Code vs. Drywall Code: The Reliability Dividing Line in AI Programming
Using the metaphor of "load-bearing code" vs. "drywall code," distinguish which code in AI programming can be rapidly experimented with and which must be rigorously reviewed. Using USB drivers as an example, analyze the risks of LLM hallucinations in core systems and provide a practical method for drawing the line in real projects.

Logit Bias: Weighting LLM Vocabulary to Precisely Control Output
A deep dive into logit bias in LLMs: precisely control model word choice by adjusting token logit scores—boost specific words or suppress unwanted expressions, with OpenAI API code examples and usage boundary notes.
Adding Read-Only Guardrails to LLM-Generated SQL with sqlglot
Use sqlglot to parse SQL and build read-only guardrails for LLM-generated queries: SELECT-only validation, node blocking, file-read blocking, CTE-aware allowlists, row caps, cost proxy.

Inferring L1 Backgrounds from L2 English via LLM Token Probabilities: 70B Model Achieves SOTA
New study infers L1 backgrounds from L2 English using LLM token probabilities; Llama 3.1 8B and 70B evaluated on three datasets, with 70B achieving SOTA.

Sampling, Mixing, or Verifying? Optimal Allocation of Inference Compute Under Imperfect Verifiers
SPLIT uses a small amount of labeled pilot data to precisely plan inference-time compute allocation, approaching hindsight-optimal across seven benchmarks and 26 models, and reveals when more LLM reviewers can reduce accuracy.

Breakthrough in Training-Free Multilingual Text Embeddings: PRSR Enables More Precise Cross-Lingual Alignment in LLMs
This article introduces PRSR, a training-free multilingual text embedding method that removes language-specific variation via paired-residual subspace removal, improving cross-lingual alignment across 18 languages and 200+ evaluations.