#NVIDIA
68 related articles
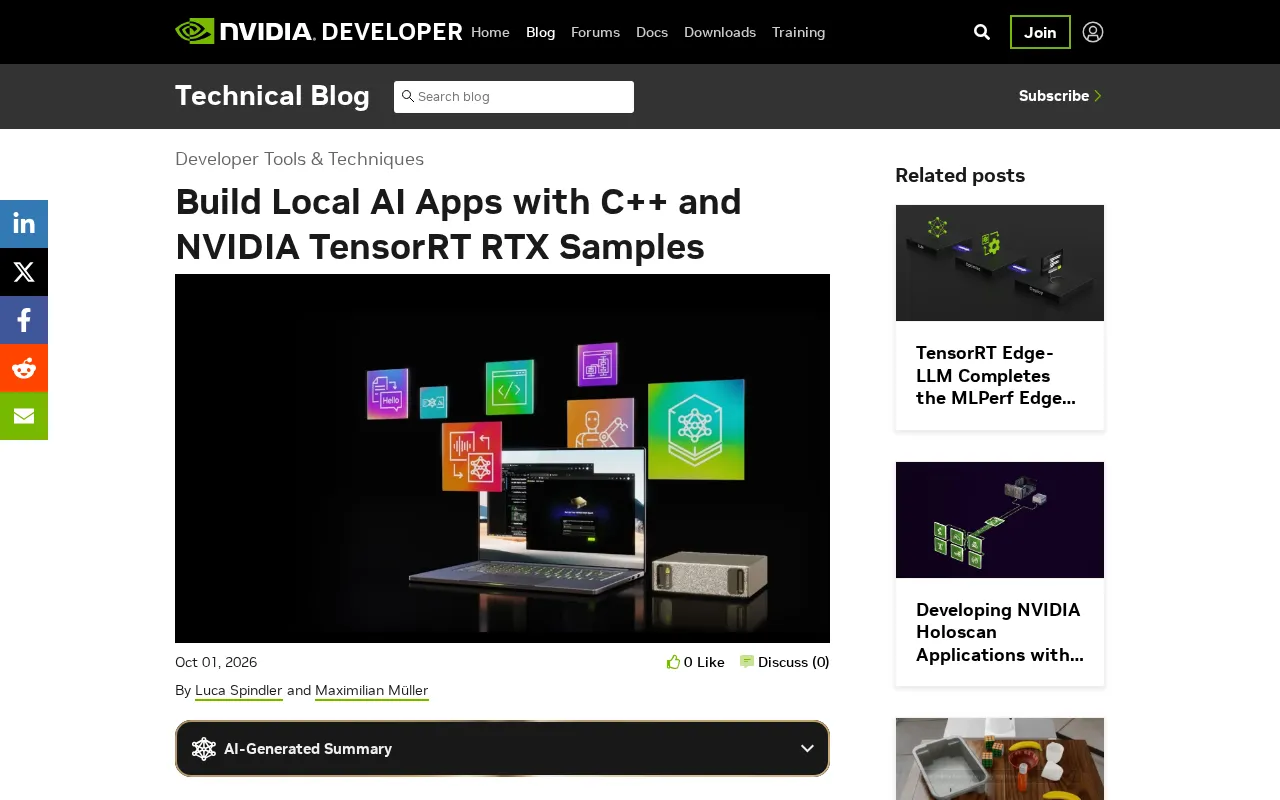
A Practical Guide to Building Local AI Apps with C++ and NVIDIA TensorRT RTX
Learn how to build high-performance local AI apps using C++ and NVIDIA TensorRT RTX. Covers portable model formats, GPU acceleration, and the Do Inference Now sample project.

Deploying HSTU Generative Recommender Systems in Production: A Deep Dive into NVIDIA Dynamo-Triton
NVIDIA's Dynamo-Triton framework enables production deployment of HSTU-based generative recommender systems, combining autoregressive modeling with efficient inference for industrial-scale personalization.

Tracing Agent Execution Paths with NVIDIA NeMo Relay: Making Efficiency Visible
NVIDIA NeMo Relay traces Agent Harness execution behavior, helping developers uncover inefficient paths behind task completion. Learn why process-level observability matters.
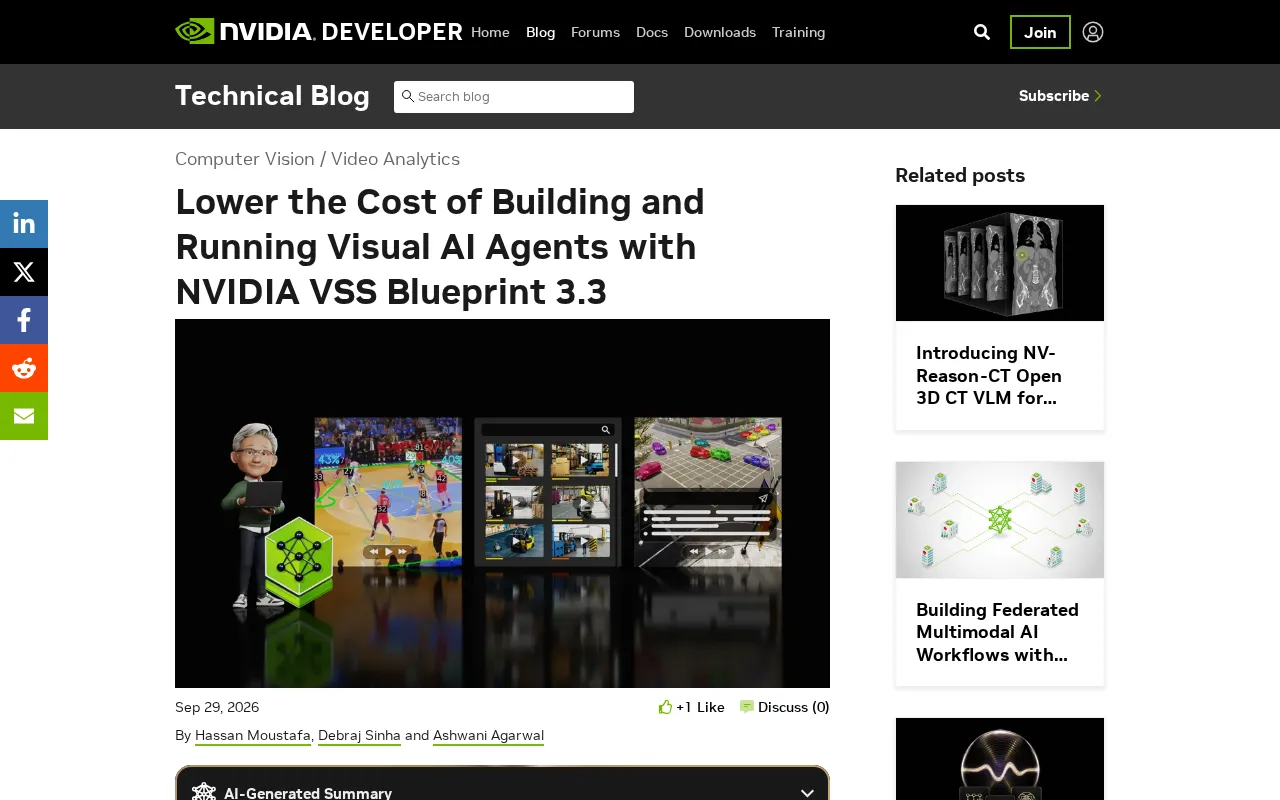
NVIDIA VSS Blueprint 3.3: Reducing the Cost of Building and Running Visual AI Agents
NVIDIA VSS Blueprint 3.3 cuts the cost of building and running visual AI agents. Learn how this video search and summarization reference architecture lowers TCO.
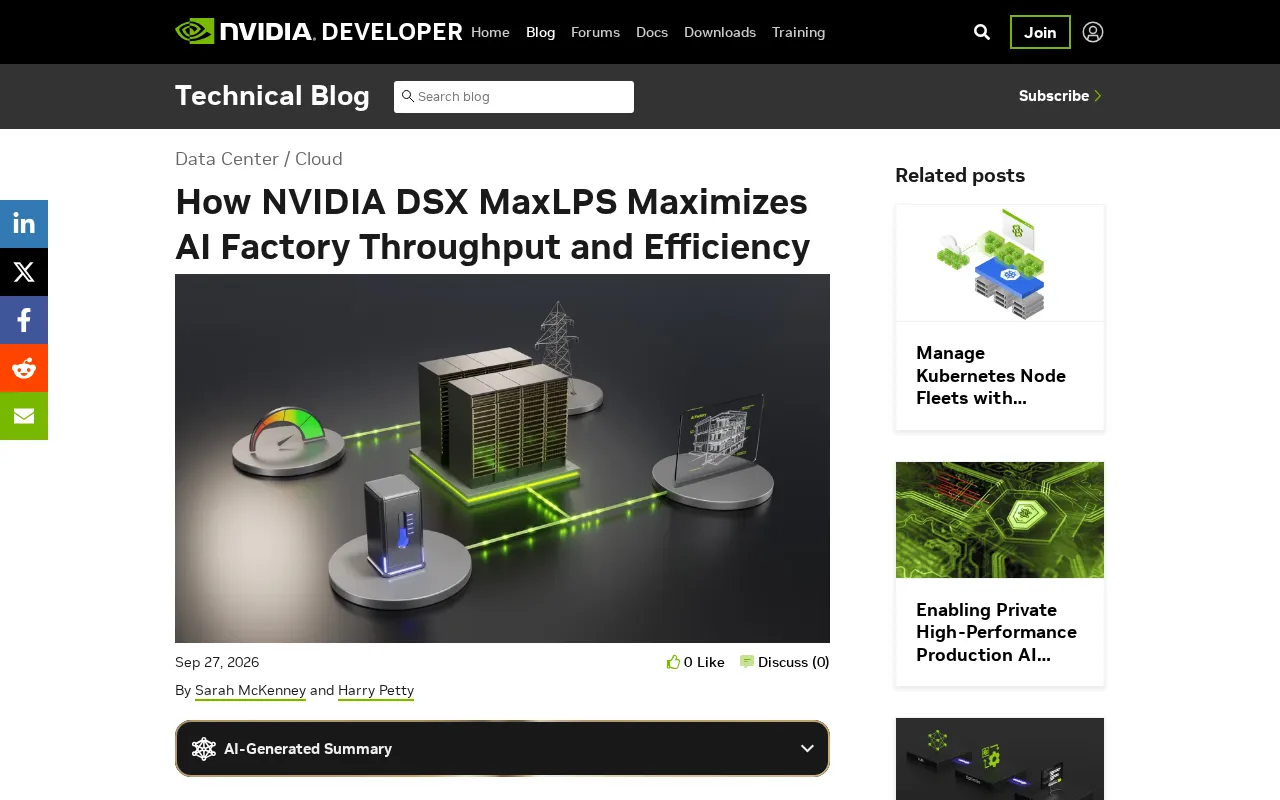
NVIDIA DSX MaxLPS: How to Squeeze Every Watt Out of an AI Factory
NVIDIA DSX MaxLPS uses dynamic power scheduling to break AI factories' peak-provisioning waste, fitting more GPUs into the same power budget to maximize compute throughput and energy efficiency.

NVIDIA PAIR: Turn Your Idle Home Computers Into a Local AI Cluster
NVIDIA PAIR is free software that pools idle compute from your home devices into a local AI cluster, routing agent tasks dynamically — with full privacy and Apple support.
OpenAI Jalapeño Inference Chip First Look: The Battle Is Won or Lost Per Token Per Watt
OpenAI's Jalapeño inference chip debuts with 1.5–1.9x tokens-per-watt gains over NVIDIA GB200/GB300 across gpt-oss, DeepSeek R1, and Kimi K2 benchmarks. A clear-eyed analysis of test boundaries, Prefill/Decode architecture, and the inference chip competitive landscape.
NodeWright: Solving the Kubernetes Node Cluster Management Problem
NVIDIA's NodeWright brings Kubernetes node configuration — kernel params, packages, storage, and security — into a declarative framework, solving GPU cluster drift at scale.

NVIDIA Confidential Computing: High-Performance AI Inference Without Sacrificing Privacy
How does NVIDIA Confidential Computing protect data privacy in GPU-accelerated AI inference without sacrificing performance? Explore TEEs, hardware encryption, attestation, and regulated industry use cases.

NVIDIA DLSS 5 Released: Breaking Down 3D-Guided Neural Rendering and New RTX Kit Capabilities
NVIDIA launches DLSS 5 with 3D-Guided Neural Rendering, alongside NVIDIA ACE updates and new RTX Kit capabilities, offering developers more realistic lighting and finer image control.

Accelerating ROS 2 Nodes with AI Agents: A Practical Look at NVIDIA Isaac ROS
NVIDIA Isaac ROS uses AI Agents to accelerate ROS 2 node development. Learn why GPU kernels alone don't speed up ROS 2 graphs, and how zero-copy optimizes data flow.

TensorRT Multi-Device Inference: Simplifying Multi-GPU Model Deployment in Dynamo-Triton
NVIDIA introduces TensorRT Multi-Device Inference in Dynamo-Triton, simplifying large model deployment across multiple GPUs and lowering the engineering barrier for production generative AI serving.

NVIDIA Earth-2: An AI Platform for Weather Decision-Making Powered by Real-Time Observations
NVIDIA Earth-2 uses GPU acceleration and AI weather models to help energy, logistics, and agriculture industries turn real-time observations into high-resolution weather decisions.

NVIDIA Isaac for Healthcare: Training Medical Robots with GPU-Accelerated Medical Physics Simulation
NVIDIA Isaac for Healthcare introduces a GPU-native medical physics simulation platform using digital twins, classical physics, and Cosmos generative world models to train surgical and interventional robots at scale.

NVIDIA NeMo Data Designer: An Open-Source Framework for Multimodal Synthetic Data Generation
Deep dive into NVIDIA's open-source NeMo Data Designer (NDD): declarative config, preview-revision loops, plugin extensibility, and runtime scheduling for multimodal synthetic data generation.

TensorRT Edge-LLM Benchmarked: Jetson AGX Thor Runs MLPerf Edge Agentic Workloads 6.4x Faster
NVIDIA TensorRT Edge-LLM achieves 6.4x speedup on Jetson AGX Thor for MLPerf edge Agentic benchmarks. Explore how software-hardware co-optimization enables real-time agent deployment at the edge.

NVLink 6 Multi-Layer Resiliency: How NVIDIA Keeps AI Factories Running
NVIDIA NVLink 6 uses multi-layer resiliency to sustain AI factory compute through link redundancy, fault isolation, and system-level monitoring at hyperscale.
NVIDIA FLARE Federated Learning in Practice: Scaling Deployments Across Docker, K8s, and Slurm
NVIDIA FLARE is an open-source federated learning framework supporting Docker, Kubernetes, and Slurm deployments, helping healthcare and finance industries scale FL from prototype to production.

Accelerating Dropless MoE Training in JAX: A Deep Dive into NVIDIA Transformer Engine
Learn how NVIDIA Transformer Engine accelerates Dropless MoE training in JAX, covering MoE architecture, token dropping, FP8 precision, and grouped GEMM optimizations.
HP ZGX Fury Now Available for Order: Powered by GB300 Superchip and 748GB Unified Memory
HP ZGX Fury AI workstation is now available, featuring the NVIDIA GB300 Superchip and 748GB unified memory for local large-scale AI model development.