#RAG
318 related articles

RAG Full-Stack Development: From Core Concepts to the Five Key Stages Explained
A beginner's guide to RAG: covers chunking, indexing, retrieval, reranking, and generation — plus vectors, Embedding, and vector databases. Build enterprise knowledge bases with confidence.

Enterprise Knowledge Retrieval Benchmarking: Why AI Agents Fail on Real-World Data
Why do AI agents fail on real enterprise knowledge bases? This article examines the gap between messy corporate data and clean benchmark datasets, and offers practical guidance for enterprise RAG evaluation.

Getting Started with AI Agent Development: A Practical Breakdown of the Four Core Modules
A beginner's guide to AI Agent development: break down the four core modules — prompt architecture, tool calling, RAG, and ReAct workflows — to fix hallucinations, loops, and unreliable output.
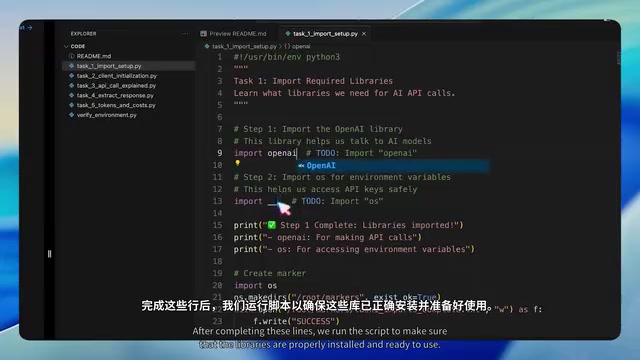
Building Production-Grade AI Systems from Scratch: A Complete Guide to LLMs, RAG, and Multi-Agent Workflows
A complete breakdown of production-grade AI systems: from LLM context windows and embeddings to RAG, LangChain, LangGraph, and MCP — built around one enterprise doc assistant project.

AI Quality Inspection for 400K Tickets: An Intern's Architecture Decisions
An intern solo-building an AI QA system for 400K support tickets. See how to split scoring into rule engine, embedding classifier, and RAG+LLM layers on a tight budget.
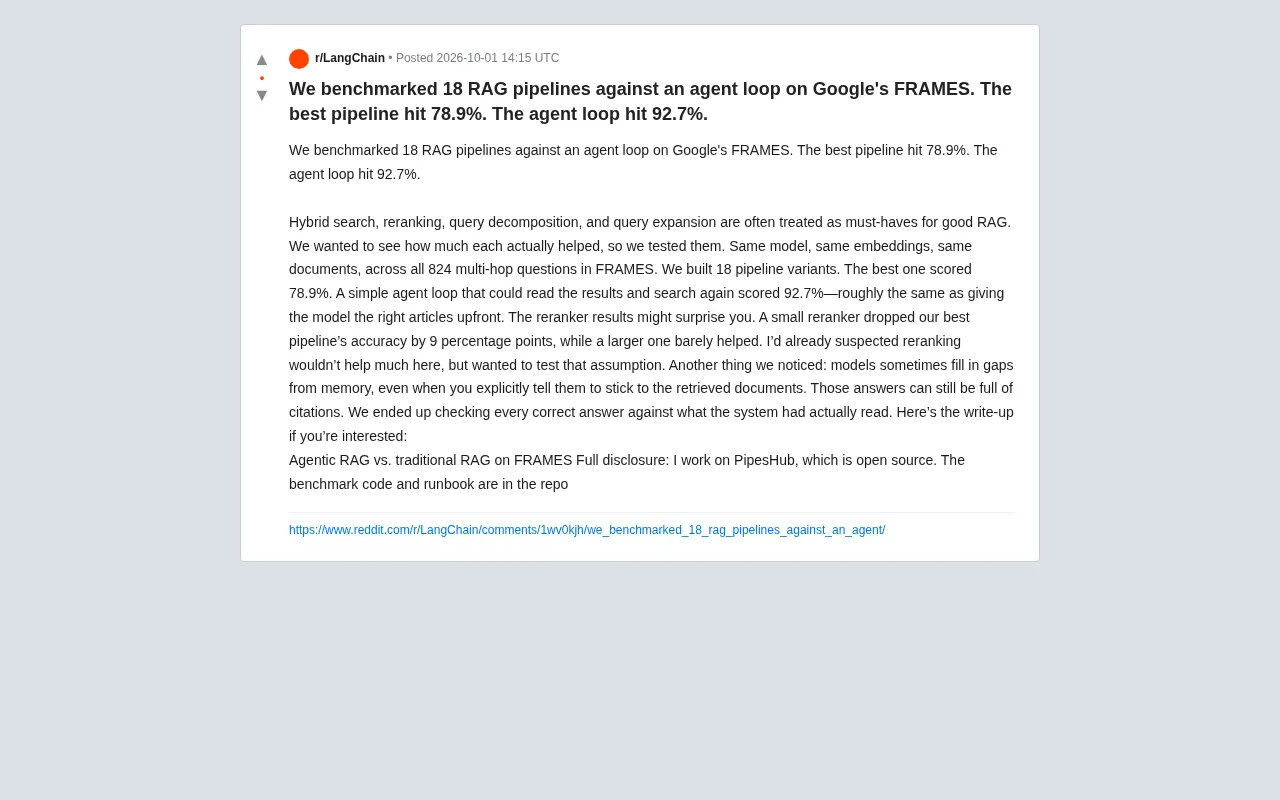
Agentic RAG Benchmark: Agent Loop Crushes Traditional Pipelines with 92.7% Accuracy
PipesHub tested 18 RAG pipelines on Google FRAMES: the best traditional pipeline hit 78.9%, while an Agent loop scored 92.7%. Key findings: rerankers can hurt accuracy, and models hallucinate cited answers.
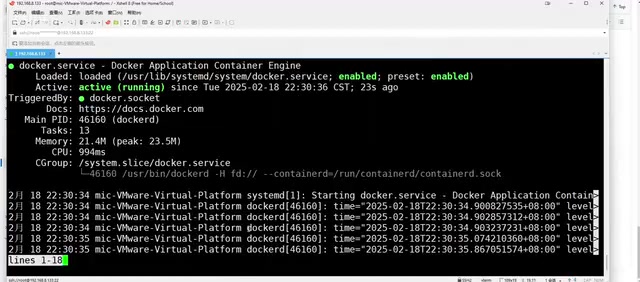
DeepSeek + Ollama + AnythingLLM: Complete Guide to Local RAG Knowledge Base Deployment
Step-by-step guide to building a private local RAG knowledge base on Ubuntu using Ollama, AnythingLLM, and DeepSeek — covering Docker setup, model download, remote access config, and common pitfalls.

Staged RAG Architecture in Practice: Making Retrieval Failures Explicit and Controllable
A staged RAG architecture using BGE-M3 hybrid retrieval, BGE reranking, relevance gating, and context quality filtering to make retrieval failures explicit — built on Qdrant and local DeepSeek R1 7B.
AI Agent Development: From Zero to Enterprise-Grade Deployment
A practical breakdown of AI Agent development: framework selection, MCP tool calling, RAG data preparation, and production evaluation — what actually matters for enterprise deployment.

Sieve and Sage: Teaching Retrieval-Augmented Models to Know What They Don't Know
arXiv paper proposes Sieve and Sage framework for RALMs, using a two-stage pipeline to enable reliable abstention — boosting accuracy by up to 69.4 pts and speed by 1.99×.

Retrieval Is a Decision Problem, Not a Similarity Problem: Lessons from GPT Researcher Experiments
Retrieval isn't just similarity matching — it's a decision problem. GPT Researcher experiments show decision-based retrieval raises relevant context from 46% to 73%, reshaping RAG and AI Agent design.

Open-Source Intelligent Business Data Assistant: A Deep Dive into the RAG+MCP+RBAC Memory-Driven Architecture
An open-source memory-driven BI assistant combining RAG, MCP tool protocol, and RBAC built on FastAPI + React — featuring persistent analytical memory, knowledge grounding, evidence-backed answers, and enterprise security.

Enterprise AI Customer Service in Practice: Building a Full Pipeline with RAG + Agent + Ontology + Human Review
A full walkthrough of building enterprise AI customer service: how Agent orchestration, RAG retrieval, Ontology relationship queries, and human review work together across order lookup, knowledge search, auto-reply, and exception escalation.
Where Does Your RAG Pipeline Actually Break: Retrieval or Generation?
When your RAG pipeline underperforms, is it retrieval or generation at fault? This guide breaks down failure patterns, diagnostic methods, and layered evaluation strategies for both stages.

AI Agent Memory Optimization in Practice: Moving Beyond Context Window Stuffing
How should you design an efficient memory system for AI Agents? A developer shares their journey from context stuffing to persistent memory layers, comparing vector RAG, graph-based, and metadata filtering approaches to cut Token costs and boost speed.
How to Choose a High-Quality AI Agent Development Course: 5 Practical Screening Criteria
How do you avoid wasting money on low-quality AI Agent courses? Here are 5 practical screening criteria: full delivery pipeline, resume-worthy projects, real engineering perspective, update frequency, and mentorship support.

Corrective RAG (CRAG) in Practice: Building a Compliance Research Assistant That Self-Validates
How does CRAG make a compliance assistant self-check before answering? A deep dive into a LangGraph + Qdrant self-correcting RAG Agent with document scoring, query rewriting, and bounded retries.

Running RAG on 8GB RAM with Frequent OOM? A Practical Guide to Optimizing Docling's Memory Usage for PDF Processing
Running Docling on 8GB RAM and hitting OOM while building RAG? Learn batching strategies, Docling memory optimization, and how to decouple local testing from AWS deployment.

How RAG Systems Handle Dynamic State, Temporal Data, and Conflicting Records
How do RAG systems handle dynamic state, temporal data, and conflicting records in production? Explore metadata filtering, versioning, bitemporal modeling, conflict resolution, and GraphRAG strategies.

Qwen3 + RAGFlow: A Zero-Cost Guide to Building a Local Knowledge Base from Scratch
Step-by-step guide to building a local knowledge base AI assistant using Ollama, Qwen3, and RAGFlow at zero cost — covering Docker setup, model integration, vector retrieval, and hallucination elimination.