#大语言模型
305 related articles

MemFold Soft Memory: Fixed 256 Vectors Double Usable Context and Deliver 4x Speedup
MemFold uses fixed 256 latent vectors to compress long conversation history, doubling usable context and achieving ~4x speedup while reaching top accuracy on PersonaMem-128K and other benchmarks.

Can Language Models Learn When to Refuse? Experiments with Policy Learning and Answer Selectors
A Qwen3-14B study explores how LLMs learn when to refuse. An answer selector raised TriviaQA coverage from 20.2% to 30.9% and cut error rate from 23.0% to 14.5%, though cross-dataset generalization remains unsolved.

Same Query, Different Answer: The Run-to-Run Variance Problem in Semantic Query Engines
A study of 1.2M model calls reveals run-to-run variance in semantic query engines: even temperature 0 can't guarantee determinism, and 21% of benchmark results change quality on re-runs.

Agentic LLM: How Large Language Models That Can Act Will Change the World
Agentic LLMs combine reasoning with real-world action, evolving AI from answering questions to autonomously executing tasks. Learn how they work, interact, and what they mean for users.

SqueezeBench: A Saturation-Resilient Benchmark for AI Mathematical Capability
SqueezeBench is a saturation-resilient AI math benchmark that maintains upper/lower bound records with dual Lean kernel verification, ensuring every success raises the bar.

LLMxRay: The Open-Source LLM Observability Tool That Turns Black-Box Model Calls Transparent
LLMxRay is an open-source LLM observability tool that helps developers trace call chains, monitor token costs, and analyze latency. Here's what it offers.
Non-Text AI Model Jev Ignites Market Frenzy: Developer TypeSafe Valued at $7.5 Billion
Just weeks after launch, non-text AI model Jev has propelled developer TypeSafe to a $7.5B valuation, promising faster speeds and far lower token consumption than LLMs.

A New Direction in ADI Architecture: Can an 8B Model Meet the Same Acceptance Bar as a 35B Model?
Cortex Agentics introduces Artificial Deterministic Intelligence (ADI), separating probabilistic LLM reasoning from deterministic governance. Experiments show an 8B model matching a 35B model under scoped context.

Local LLM Benchmark for 10-16GB GPUs: Which Models Are Actually Worth Running?
A hands-on LLM benchmark for 10-16GB GPUs covering Gemma 4, Qwen 3.6, GLM-4.7 and more — ranked by speed, coherence, slop rate, and vendor personality traits.
Dấu or Die Benchmark: Can LLMs Restore Vietnamese Tone Marks?
Vietnamese developer Tuan Nguyen built the Dấu or Die benchmark to test LLMs on restoring Vietnamese tone marks. Gemini 3.7 Flash scored a perfect 37/37, while 480B-parameter Qwen Coder ranked last.
Google Gemini 4 Argon Launches: Million-Token Output Reshapes the Flagship AI Landscape
Google launches Gemini 4 Argon with a 1M-token output limit, benchmarked against GPT-6 Astra and Claude. Explore scores, pricing, token costs, and its defender-first rollout.

REMORY: How 32 Residual Tokens Compress 8K Conversation Context
REMORY uses 32 residual soft tokens to reconstruct 8K-token conversations with 95% fidelity. Explore its encoder-decoder architecture, KL divergence training, benchmark results, 87% cost reduction, and real-world risks like token drift and adversarial attacks.

Meta-Ability: Let Code Think for the Model — A Deep Dive into CodeSmith's RLM Design
CodeSmith's RLM design explains why LLMs can't do math reliably — and the engineering logic of "letting code think for the model": LLM as translator, interpreter as calculator, with contracts, timeouts, and depth limits as guardrails.

Do LLMs Really "Understand" Language? Attention Mechanisms and the Pattern Recognition Debate
Do LLMs truly understand language or just do advanced pattern recognition? We examine the "stochastic parrot" vs. "emergent understanding" debate through the lens of Transformer attention mechanisms.
The Complete Guide to RAG (Retrieval-Augmented Generation): Core Steps for Building Production-Grade Systems
A complete guide to Retrieval-Augmented Generation (RAG): explore the core architecture combining vector search with LLMs, covering data ingestion, embedding, indexing, and key steps for building production-grade RAG systems.

Everyone Complains About AI, Yet Nobody Can Quit It: Unpacking the Paradox
Why do people criticize AI while using it more than ever? This piece unpacks the love-hate paradox through one startup's bet on output diversity as the antidote.

OrcaCyber Zero 1.5 Released: A Cybersecurity-Specialized Model with 1M Token Context
OrcaRouter launches OrcaCyber Zero 1.5, a gated cybersecurity LLM with 1M token context, 100% Cybench score, and 95.8% on CVE-Bench subset. Priced at $3/$7.5 per 1M tokens.

Qualcomm CEO's Bold Claim: 100B-Parameter AI Models Could Live Permanently on Smartphones by 2028
Qualcomm's CEO says AI firms want 100B-parameter models running on phones by 2028. We break down the memory math, thermal limits, and business motivations.
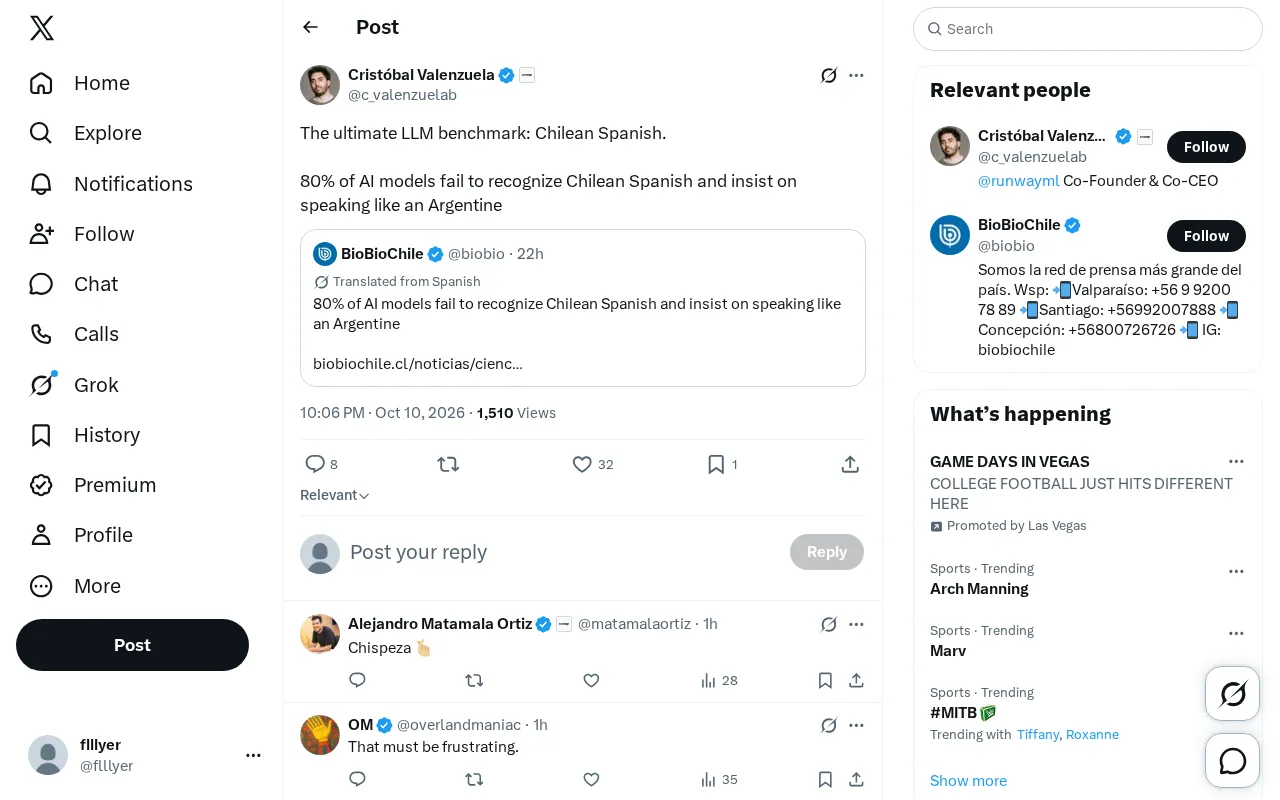
Chilean Spanish: The Overlooked Dialect Recognition Problem for LLMs
~80% of AI models fail to recognize Chilean Spanish and respond in an Argentine accent instead. This article examines data bias and the low-resource variant problem in LLMs.
Busting 7 Common AI Myths: What AI Actually Is (and Isn't)
AI doesn't think, tell the truth, or stay neutral the way you might imagine. This article busts 7 common AI myths — from hallucinations to privacy — to help you use LLMs smarter.