#AI编程
9013 related articles
GPT-OSS-120b Returning Empty Responses? A Troubleshooting Guide for Tool Calling and Reasoning Content Retrieval
Developers report GPT-OSS-120b on Azure via AzureChatOpenAI returns empty responses and fails tool calls. This article analyzes possible causes and provides troubleshooting methods for retrieving reasoning_content.
Tracing Randomness in PyTorch Training: Six Entry Points and Control Strategies
A systematic breakdown of the six entry points of randomness in PyTorch training: Python/NumPy seeds, weight initialization ordering, DataLoader generators, multi-process workers, Dropout order dependence, and GPU non-deterministic operators, with practical advice on deterministic mode configuration and statistical reproducibility.
Agent-Browser: A Browser Automation CLI for AI Agents
Vercel Labs open-sources agent-browser, a Rust-built browser automation CLI designed for AI agents, with over 45,000 GitHub stars and command-line-first browser control.
Ripple-65B: A US Open-Weight Dense Coding Model Takes On Terminal-Bench 2.1
Ricursive releases Ripple-65B Preview, an Apache 2.0 dense coding model claiming the best Terminal-Bench 2.1 score among US open-weight models. We break down the model card's claims, HN's skepticism, and which teams should test it.

Measuring Risk, Not Harm: A New Framework for Detecting Psychological Harm Risk Factors in LLM Conversations
Researchers propose "measuring risk, not harm": operationalizing LLM psychological harm risk as eight observable AI behaviors, building a synthetic multi-label corpus of 47K+ responses, and comparing embedding classifiers, LLM judging, and a cascade achieving F1 0.79 with 97.1% fewer judge calls.

Go Releases a Brand-New JSON API: The Changes Brought by jsonv2
Go's official blog releases a new JSON API (jsonv2), sparking heated discussion on Hacker News. This article covers the new API's design philosophy, performance and compatibility trade-offs, community reaction, and impact on developers.

A Hardcore Fighter Jet Simulator in the Browser: An Indie Developer's AI-Powered Hit
An indie developer built a hyper-realistic browser fighter jet simulator with Claude Opus 5.5 and fal models, drawing 25K players in two weeks and a threejs.org homepage feature. Discover the AI agent parallel workflow and cockpit detail polish.
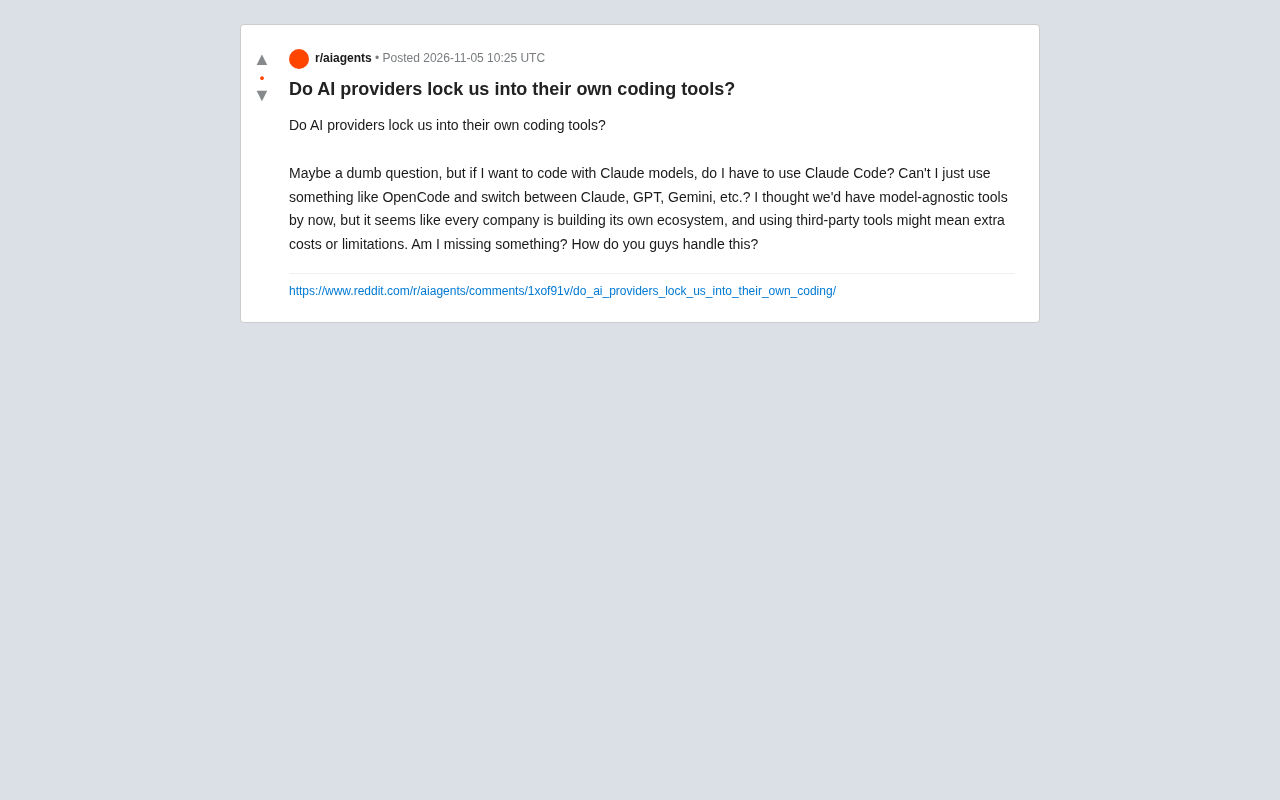
AI Coding Tools Locking You to Models? How Developers Can Avoid Lock-in
Reddit developers discuss whether AI coding tools lock you to models: Is Claude Code mandatory? Can third-party tools like OpenCode freely switch between Claude, GPT, and Gemini? An analysis of soft lock-in, third-party tool limitations, and developer strategies.

Qwen 3.8 Beats Opus at Coding—But Can Your Mac Run It?
Open-source Qwen 3.8 beats Opus 4.6 at coding at just 18GB, but how much Mac memory do you need? 24GB crashes; 32GB is the sweet spot. Full config guide inside.

Claude Code + Agent: Building a Fully Automated AI Testing Loop
Bilibili course breakdown: how test developers can use Claude Code terminal-based Agents to build a fully automated AI testing loop. Compares permission boundaries of terminal vs. device Agents, explains why enterprise projects choose Claude Code over Open Claude-type tools, and outlines the Node.js environment setup and DeepSeek model integration path.

ServerBench: Can Coding Agents Build Their Own LLM Inference Serving Systems?
ServerBench evaluates whether LLM coding agents can design specialized inference serving systems, with latency-compliant token value per dollar as the core metric; Claude Sonnet 5.5 reaches 4.87x the vLLM reference on Gemma E4B.
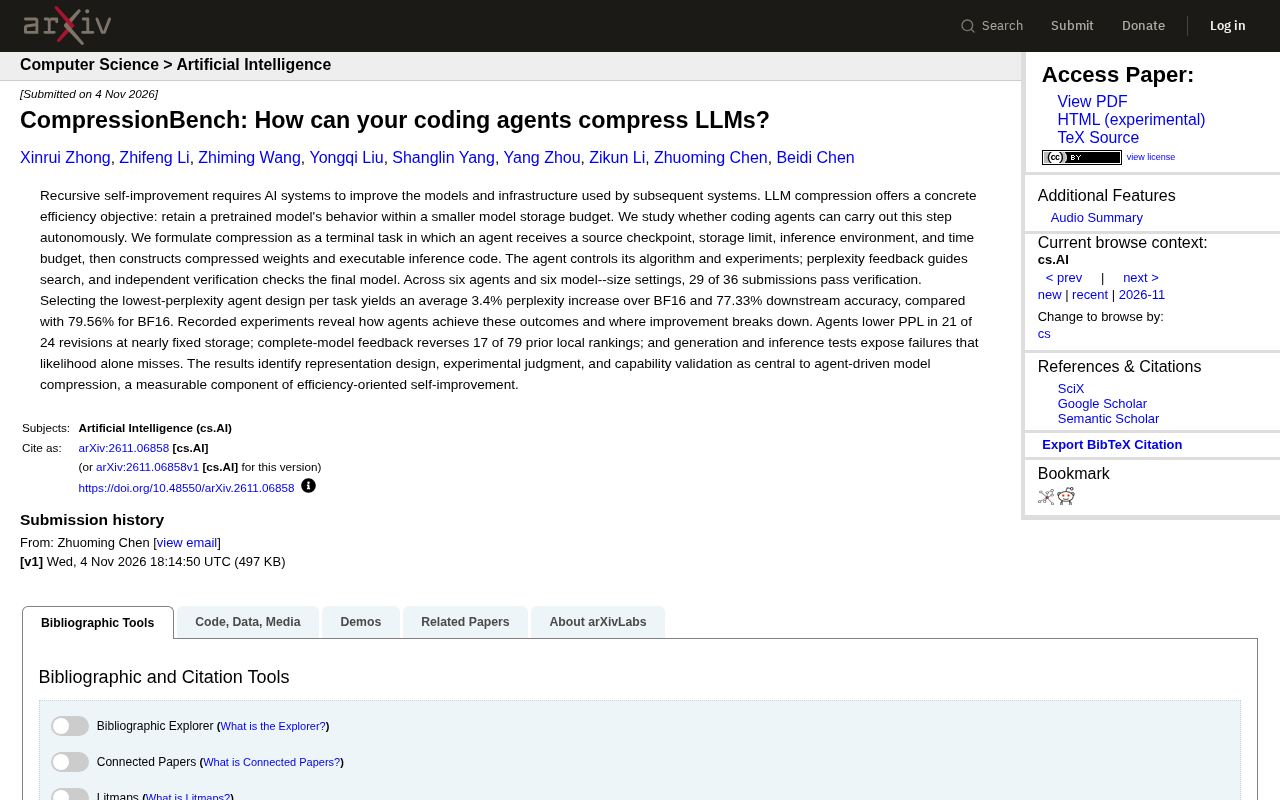
CompressionBench: Can Coding Agents Autonomously Compress LLMs?
CompressionBench studies whether coding agents can autonomously compress LLMs: 29 of 36 submissions passed verification, average perplexity rose 3.4%, and downstream accuracy was 77.33% vs. 79.56% for BF16. It highlights representation design, experimental judgment, and capability verification as core challenges.
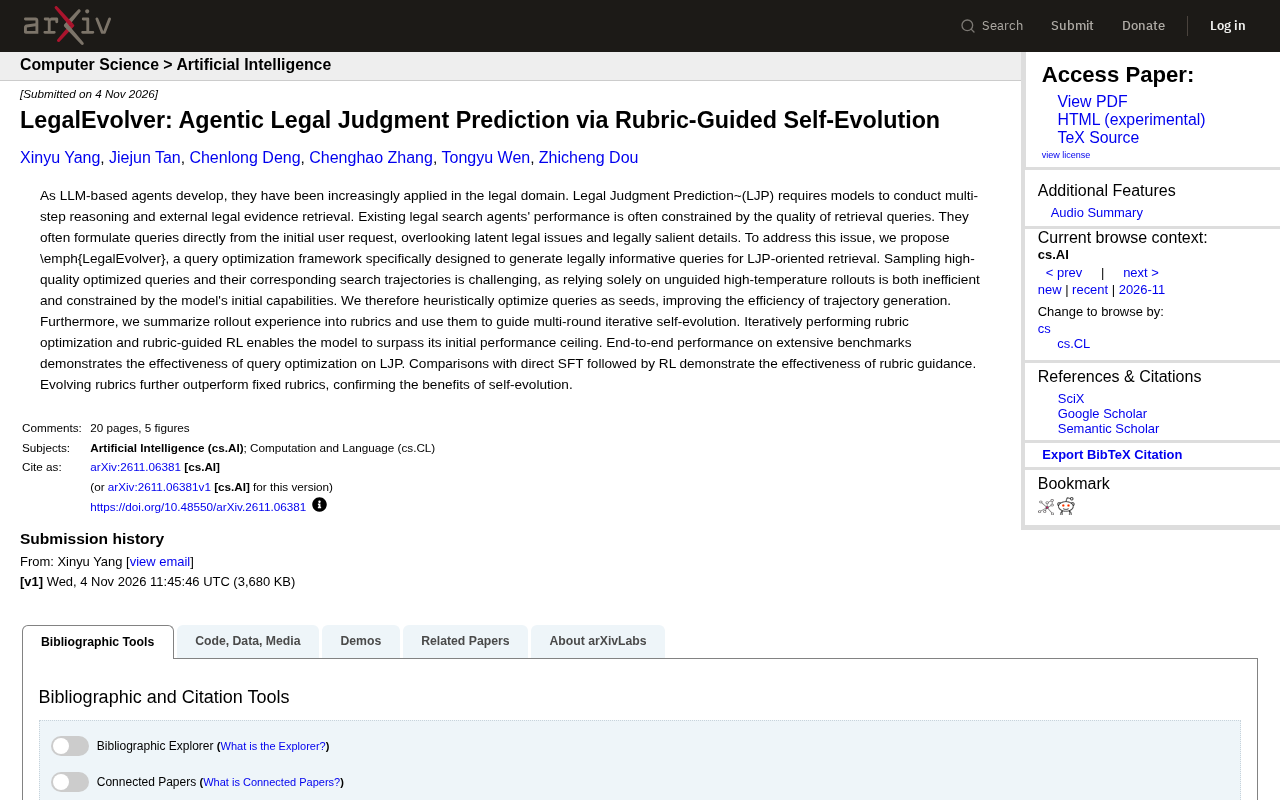
LegalEvolver: Score-Guided Self-Evolution Breaks Through Legal Judgment Prediction Bottlenecks
LegalEvolver proposes a query optimization framework that uses heuristic seed queries and rubric-guided self-evolution to solve the problem of low-quality retrieval queries in legal judgment prediction, with experiments showing it outperforms SFT+RL methods.

AI SDK Workflow 2.0.95 Update: Stream Transform API Removed
AI SDK Workflow 2.0.95 removes the experimental_transform option from WorkflowAgent.stream() and the StreamTextTransform type export, as stream transforms cannot reliably cross workflow step boundaries. This article covers the reasons, migration points, and upgrade advice.

AI SDK Vue 4.0.163 Patch Released: Full Dependency Chain Update
AI SDK Vue releases patch 4.0.163, synchronously upgrading dependencies including ai@7.0.163 and @ai-sdk/provider-utils@5.0.75. This article analyzes the practical impact of this dependency chain update.

AI SDK Voyage 2.0.75 Patch Release: What the Dependency Chain Update Means
AI SDK's Voyage Provider releases patch version 2.0.75, syncing only @ai-sdk/provider and provider-utils deps. We analyze the impact and upgrade guidance.
@ai-sdk/vue 3.0.323 Patch Released, Bringing AI SDK Updates to Vue Developers
Breaking down the @ai-sdk/vue 3.0.323 patch release: lockstep publishing with core package ai@6.0.323, signature verification details, and upgrade considerations for Vue projects.

Vercel AI SDK xAI 5.0.39 Update: Realtime Voice and Video Upload Land
@ai-sdk/xai 5.0.39 patch: XaiRealtimeModel adds server-side WebSocket config with auth, normalized usage on realtime events, word-level transcription timestamps, and typed output.uploadUrl video delivery.
AI SDK workflow-harness 1.0.174 Patch Update Analysis
Analysis of @ai-sdk/workflow-harness 1.0.174 patch update: it syncs the @ai-sdk/harness dependency, auto-published by GitHub Actions with a verified signature. The article examines the toolchain's modular layering, dependency alignment strategy, and upgrade advice for developers.
AI SDK Releases @ai-sdk/zai Patch Update: Dependency Chain Synchronized
@ai-sdk/zai releases patch 3.0.47, synchronizing @ai-sdk/provider, openai-compatible, and provider-utils dependencies. This article explains the update, its ecosystem position, and upgrade advice.